

1. What Is the Test‑and‑Learn Experimentation Framework?
The Test‑and‑Learn Experimentation Framework is a disciplined way to generate causal evidence for business decisions by running controlled experiments—most commonly A/B or geo‑tests—before scaling. It replaces opinion or correlation with “what works” under real conditions, by randomly assigning units (users, cookies, stores, regions, time slots) to a treatment and control, measuring outcomes, and deciding whether to roll out, iterate, or stop.
As a measurement, analytics, and performance management framework, it turns experimentation into an operating system: hypotheses linked to strategy, pre‑registered designs, guardrails for risk, credible analysis (power, bias control), and a shared repository of results. It applies to marketing (creative, bids, audiences), pricing and promotions, channel tactics (retail media, marketplace placements), product/UX, onboarding/CRM, and even sales motions and partner programs.
Consultants and executives use test‑and‑learn because it produces faster, safer, and more durable performance improvements than broad‑brush changes or attribution‑only decisions. The emphasis is on incremental lift, not just attributed activity—and on realized economics (contribution and pocket price), not just top‑line metrics.
2. Origin and Background
Origin: Unknown; the framework adapts the scientific method and randomized controlled trials used in medicine and industrial design since the 20th century. In business, digital experimentation scaled in the 2000s as online platforms made randomization and rapid measurement practical; offline geo‑experiments and store tests have been used even longer in retail and CPG.
Why it was adopted: Leaders needed credible, timely answers to “what works” across channels and offers in environments where user‑level tracking is noisy or biased. Experiments provide causal estimates under realistic conditions, with known uncertainty.
How it spread: Through product‑led tech firms, retail and CPG test‑and‑control practices, experimentation platforms, and consulting playbooks that institutionalized hypothesis‑driven change, pre‑registration, and governance.
3. How the Test‑and‑Learn Experimentation Framework Works
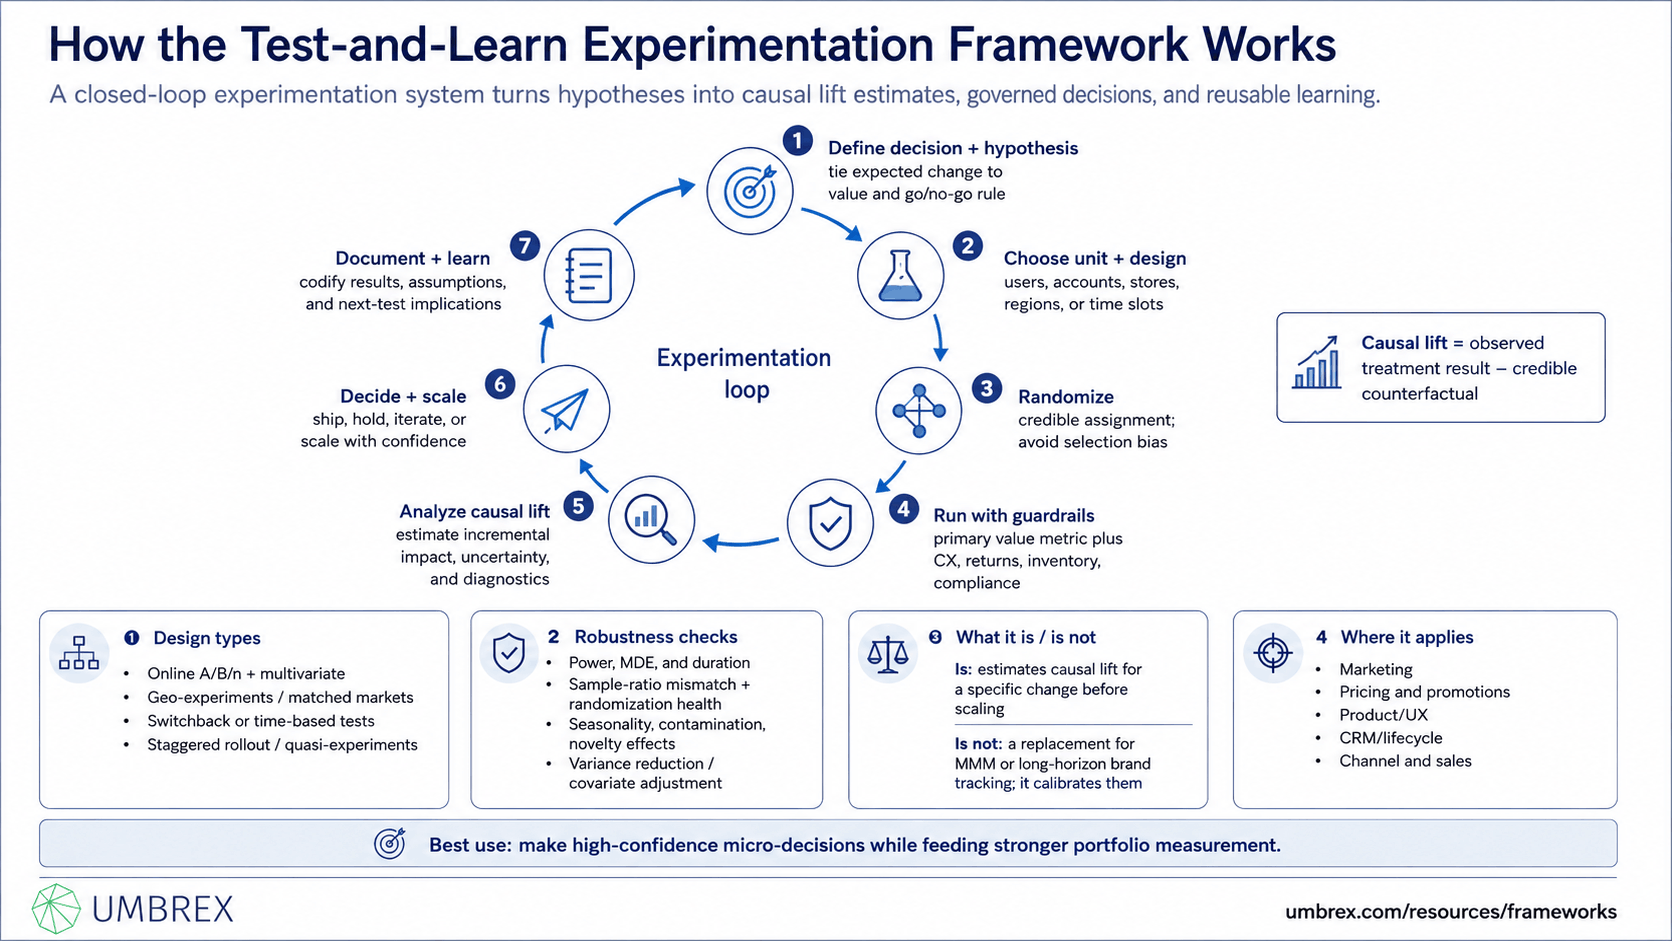
The framework follows a closed loop: define the decision and hypothesis; choose the unit and design; randomize; run with guardrails; analyze for causal lift; decide and scale; document and learn. A few concepts make it robust and scalable.
Core Elements
- Hypotheses and decision framing: State what you expect to change and why (“If we reduce promo depth by 10% with a member‑only bundle, pocket price will rise by ≥80 bps with ≤2% unit loss”). Tie the hypothesis to business value and a go/no‑go rule.
- Units and randomization: Assign users, accounts, cookies, stores, regions, or time slots to treatment/control. Ensure randomization is credible and logged; avoid selection bias (e.g., don’t let high‑value customers self‑select).
- Design types:
- Online A/B/n, multivariate (MVT): User‑ or session‑level randomization for sites/apps/ads.
- Geo‑experiments: Regions or stores as units; often with matched pairs or synthetic controls when randomization is imperfect.
- Switchback / time‑based: Alternate treatment/control across time slots when units interfere (e.g., marketplaces with single buy‑box).
- Staggered rollout (stepped‑wedge): Sequentially roll treatments to groups to combine learning and scale.
- Quasi‑experiments: Difference‑in‑differences or synthetic controls when randomization is infeasible—still hypothesis‑driven, but with stronger assumptions.
- Outcomes and guardrails: Choose one primary metric tied to value (incremental revenue, conversion, CLV proxies, pocket price) and a small set of guardrails (CX, returns, inventory, partner compliance) to prevent harmful wins.
- Power and duration: Estimate minimum detectable effect (MDE), variance, and the sample/time needed to reach a decision with acceptable error rates. Under‑powered tests frequently produce “inconclusive” or spurious results.
- Bias control and diagnostics: Check for sample ratio mismatch (SRM), randomization health, seasonality, contamination/interference, and novelty/learning effects. Use variance reduction (e.g., CUPED/covariate adjustment) when appropriate.
- Analysis and decision rules: Pre‑specify how you will analyze (frequentist with fixed horizon or sequential rules; or Bayesian credible intervals) and what constitutes ship/hold/iterate. Avoid “p‑hacking” and uncontrolled peeking.
What It Is (and Is Not)
- Is: A way to estimate causal lift for a specific change under realistic conditions—before scaling.
- Is not: A replacement for portfolio models (MMM) or long‑horizon brand measurement; rather, it calibrates them and provides micro‑level decisions.
Where It Applies
- Marketing: Creative, audience, bid/placement strategy, landing page, retail media windows, influencer formats.
- Pricing & promotions: Depth/frequency, thresholds (free shipping), bundles, price fences (member‑only), marketplace price tests (within MAP/compliance).
- Product/UX: Navigation, onboarding flows, paywall, feature gating, performance improvements.
- CRM/Lifecycle: Trigger timing, incentive types, win‑back offers, cadence.
- Channel/sales: Partner incentives, MDF constructs, sales scripts, enablement, store planograms.
4. When to Use the Framework
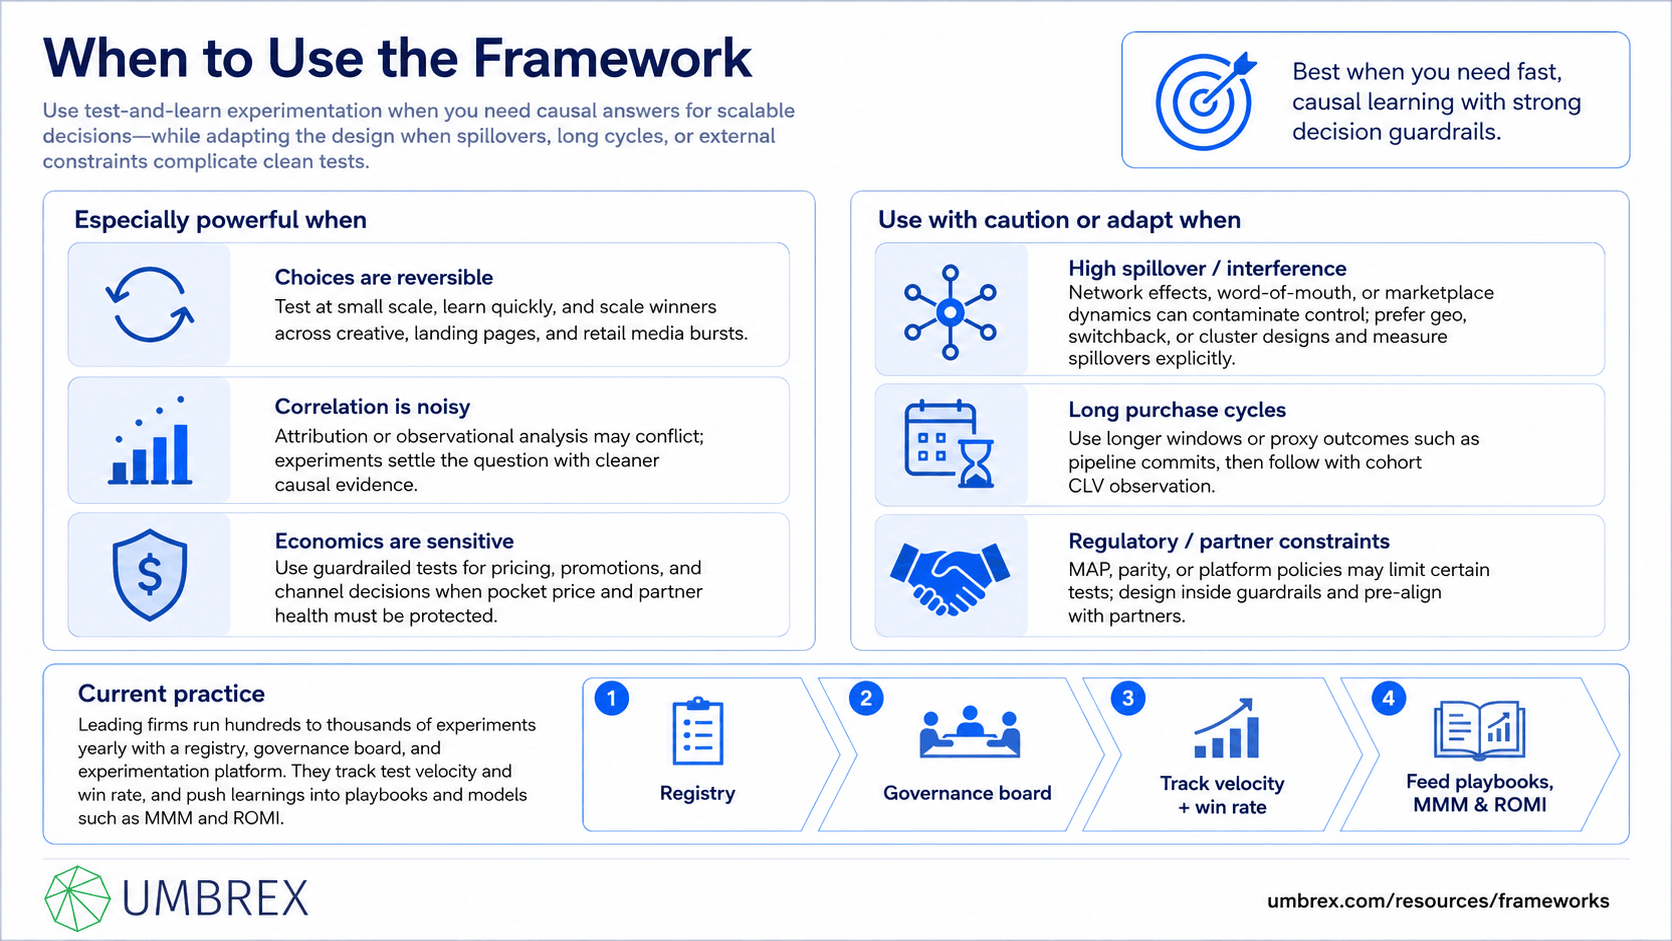
Especially powerful when:
- Choices are reversible: You can test at small scale, learn quickly, and scale winners (creative, landing pages, retail media bursts).
- Correlation is noisy: Attribution or observational analysis provides conflicting signals; experiments settle the question.
- Economics are sensitive: Pricing/promo and channel tests where pocket price and partner health must be protected via guardrails.
Use with caution or adapt when:
- High spillover/interference: Network effects, word‑of‑mouth, or marketplace dynamics can contaminate control; prefer geo/switchback or cluster designs and measure spillovers explicitly.
- Long purchase cycles: Use longer windows or proxy outcomes (pipeline commits) and follow on with cohort CLV observation.
- Regulatory/partner constraints: MAP, parity, or platform policies may limit certain tests; design inside guardrails and pre‑align with partners.
Current practice: Leading firms run hundreds to thousands of experiments yearly with a registry, governance board, and an experimentation platform. They track “test velocity” and “win rate,” and they push learnings into playbooks and models (MMM/ROMI).
5. How to Apply the Test‑and‑Learn Experimentation Framework: Step‑by‑Step
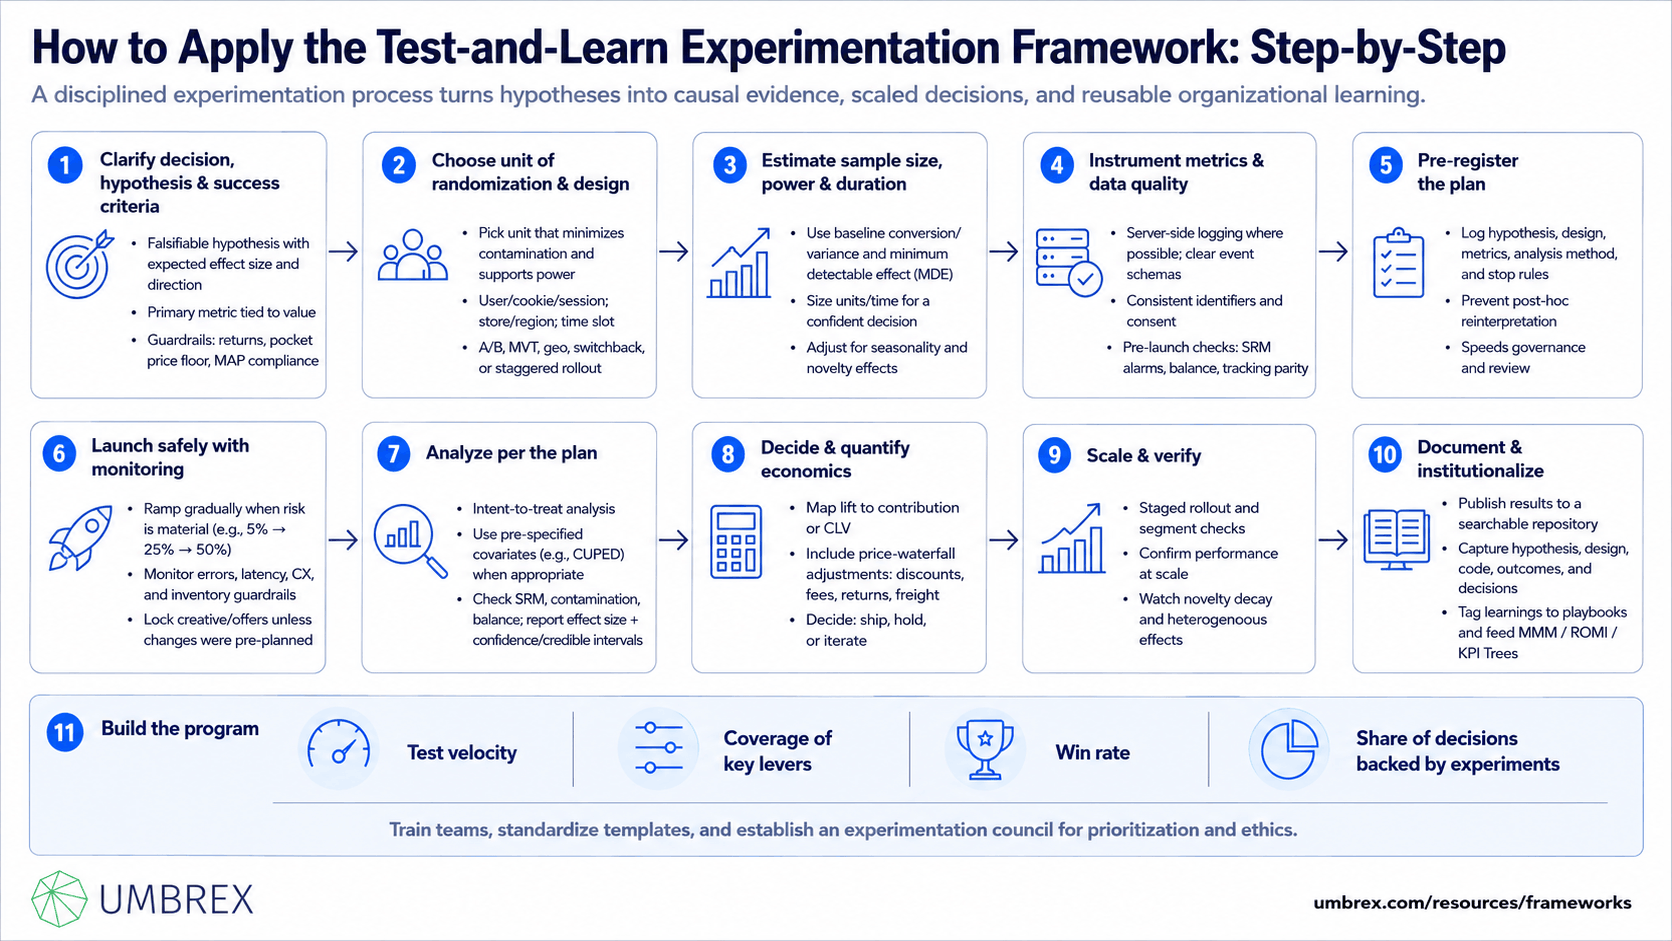
- Clarify the decision, hypothesis, and success criteria
Define the business choice and articulate a falsifiable hypothesis with effect size and direction. Specify the primary metric (e.g., incremental contribution per session) and guardrails (e.g., returns ≤ baseline, pocket price ≥ floor, partner MAP compliance).
- Choose unit of randomization and design
Pick the smallest unit that minimizes contamination and supports power (user vs cookie vs session; store vs region; time slot). Select A/B, MVT, geo, switchback, or staggered rollout based on feasibility and interference risk.
- Estimate sample size, power, and duration
Using baseline conversion/variance and the minimum effect worth detecting (MDE), estimate how many units/time you need to reach a confident decision. Adjust for seasonality and expected novelty effects.
- Instrument metrics and data quality checks
Implement server‑side logging where possible; define event schemas; ensure consistent identifiers and consent. Build pre‑launch checks (SRM alarms, randomization balance, tracking parity) and in‑flight guardrails.
- Pre‑register the plan
Record the hypothesis, design, metrics, analysis method, and stop rules in a test registry. This prevents post‑hoc reinterpretation and speeds review.
- Launch safely with monitoring
Ramp gradually if risk is material (e.g., 5% → 25% → 50% exposure). Monitor guardrails (errors, latency, CX, inventory). Lock creative/offers to avoid mid‑test changes unless planned.
- Analyze per the plan
Use intent‑to‑treat analysis; adjust for pre‑specified covariates (e.g., CUPED) to reduce variance. Check diagnostics (SRM, contamination, balance). Report effect sizes with confidence/credible intervals; avoid ad‑hoc peeking unless using valid sequential methods.
- Decide and quantify economics
Map lift to contribution or CLV, including price waterfall adjustments (discounts, fees, returns, freight). Decide: ship (scale), hold (gather more data), or iterate (refine hypothesis). Document risks and next tests.
- Scale and verify
Roll out with staged ramp; confirm performance at scale and across segments. Watch for novelty decay and heterogenous effects; keep a lightweight “post‑ship” check.
- Document and institutionalize
Publish results to a searchable repository: hypothesis, design, metrics, code, outcomes, decision, and links to subsequent tests. Tag learnings to playbooks (e.g., promo design, retail media). Feed back into MMM/ROMI and KPI Trees.
- Build the program
Set KPIs for experimentation: test velocity, coverage of key levers, win rate, share of decisions backed by experiments. Train teams, standardize templates, and establish an experimentation council for prioritization and ethics.
6. Example: Experimentation in Action
Company: “CascadeLiving,” a $400M D2C + retail home comfort brand with marketplaces and national retail partners.
Problems: CAC had risen; site relied on blanket coupons; retail partners complained about coupon leakage; pocket price was down 120 bps. The team needed to improve contribution without harming unit volume or partner relations.
Tests:
- Online A/B (D2C): Replaced sitewide 15% off with a member‑only bundle (free filter + 5% off) and improved “free shipping” threshold messaging. Primary: contribution/session; guardrails: conversion, returns, CX.
- Geo‑experiment (Retail): Reduced promo depth from 20% to 15% in matched markets, added retail media bursts during launch weeks. Primary: sell‑through; guardrails: retailer margin, buy‑box, MAP compliance.
- Marketplace switchback: Alternated price‑plus‑bundle vs discount in weekly slots to avoid permanent price signaling. Primary: contribution/order; guardrails: buy‑box win rate, rating trends.
Results (6–10 weeks):
- D2C A/B: Contribution/session +10.8% with conversion −0.7 pts (ns); returns unchanged; member sign‑ups +18%.
- Retail geo: Sell‑through −1.9% (ns) with pocket price +95 bps; aligned retail media restored share during key weeks; retailer margins improved and complaints dropped.
- Marketplace switchback: Contribution/order +7.4%; buy‑box win unchanged; ratings steady.
Decisions: Scaled bundle + shipping threshold messaging; set promo depth caps; replaced broad D2C coupons with single‑use codes; synchronized retail media with launch windows. MMM the next quarter incorporated measured lifts; ROMI improved from 1.18 to 1.47; pocket price +110 bps without sacrificing growth.
7. Strengths and Limitations
Strengths
- Causal clarity: Estimates incremental impact, not correlation.
- Speed and focus: Rapid cycles produce compounding gains; small tests avert costly mistakes.
- Risk management: Guardrails and staged ramps protect CX, partners, and margin.
- Portability: Works online and offline (geo/store/time‑based), across marketing, pricing, product, and sales.
Limitations
- Power and scope: Small or slow businesses may lack sample for reasonable MDEs; long cycles delay readouts.
- Interference: Spillovers contaminate controls (marketplaces, social networks); requires careful design.
- External validity: A win in one cohort/region may not generalize; follow‑on tests at scale are needed.
- Operational cost: Requires instrumentation, governance, and cultural adoption; parallel tests can interact.
8. Common Pitfalls (and How to Avoid Them)
- Peeking and p‑hacking
What goes wrong: Early looks or multiple unplanned cuts produce false positives.
How to avoid: Pre‑register analysis; use fixed horizons or valid sequential rules; report intervals and uncertainty. - Under‑powered tests
What goes wrong: Inconclusive results; teams wrongly ship or kill ideas.
How to avoid: Plan MDE and duration; pool units (geo rather than store) or use variance reduction (CUPED); prioritize bigger levers. - Sample ratio mismatch (SRM)
What goes wrong: Broken randomization or tracking skews results.
How to avoid: Monitor SRM in real time; halt and fix instrumentation before reading. - Contamination and interference
What goes wrong: Users see both variants; spillovers bias effects.
How to avoid: Use user‑level randomization, switchback, or geo designs; measure cross‑exposure; widen separation. - Seasonality and novelty effects
What goes wrong: Tests coincide with peaks/lulls or early novelty spikes.
How to avoid: Balance by calendar; run long enough to pass novelty; stagger starts. - Wrong success metric
What goes wrong: Optimize clicks or top‑line revenue; margin and pocket price suffer.
How to avoid: Use contribution/CLV as primary, with price waterfall adjustments; include guardrails. - Mid‑test changes
What goes wrong: Creative/price changes invalidate results.
How to avoid: Freeze variant content or re‑start; document any deviations. - No registry or documentation
What goes wrong: Duplicate tests; institutional amnesia; cherry‑picking.
How to avoid: Maintain a test registry, templates, and searchable results with code and decisions.
9. How the Experimentation Framework Relates to Other Frameworks
- ROMI: Experiments provide lift estimates that convert to contribution/CLV ROMI and payback; they de‑risk reallocation decisions.
- Marketing Mix Modeling (MMM): Use experimental results to calibrate MMM coefficients; MMM generalizes beyond test cells, accounts for price/promo, and estimates long‑run effects and diminishing returns.
- Attribution Modeling: Attribution guides weekly optimization; experiments validate incrementality and correct bias (e.g., affiliates, branded search).
- Marketing KPI Tree: Tests target high‑leverage nodes (conversion, AOV, price realization) and quantify sensitivities.
- Brand Tracking Funnel: Experiments can move intermediate brand outcomes (consideration, preference) and validate the link to revenue; MMM translates those effects to long‑run sales.
- Price Waterfall & Promotional Mechanics: Pricing/promo tests must be evaluated on pocket price and margin, not just volume; fenced promotions often beat blanket discounts in experiments.
- SOV–SOM: Use tests to confirm whether increased SOV (creative/format shifts) meaningfully moves funnel metrics and sales before committing to sustained ESOV.
10. Key Takeaways
- The Test‑and‑Learn Experimentation Framework delivers causal, decision‑grade evidence—fast—by running controlled tests with clear hypotheses, guardrails, and analysis plans.
- Design matters: pick the right unit and method (A/B, geo, switchback), plan power and duration, and monitor for SRM, contamination, and seasonality.
- Measure what the business values: contribution/CLV and pocket price, with CX and partner guardrails—not just clicks or attributed revenue.
- Institutionalize experimentation: a registry, governance, and a repository turn one‑off tests into a compounding capability; feed results into MMM, ROMI, and KPI Trees.
- Use tests alongside MMM and attribution: experiments calibrate models and resolve disputes; models scale insights and guide portfolio allocation.
11. FAQs About the Test‑and‑Learn Experimentation Framework
How big does my sample need to be and how long should I run?
It depends on baseline rates, variance, and the minimum effect you care about (MDE). As a rule, plan for enough users or time to detect that MDE with ≥80% power. If traffic is limited, consider geo designs, variance reduction (CUPED), or testing larger levers.
Frequentist or Bayesian?
Either can work. Frequentist approaches are standard and easy to govern; Bayesian analysis provides intuitive credible intervals and supports continuous monitoring when properly set up. What matters most is pre‑specification, calibration, and governance against p‑hacking.
Can we test in marketplaces and with retail partners?
Yes, within policy. Use geo or time‑slot (switchback) designs, respect MAP/parity, and coordinate retail media and inventory. Evaluate on sell‑through and pocket price, not just orders.
What about interference and spillovers?
If users can see both variants or influence each other, move to cluster randomization (stores/regions), switchback, or staggered rollout, and measure cross‑exposure. Avoid cookie‑level tests when login/account identity is available.
How do we capture long‑term effects?
Run follow‑up windows for retention/CLV or repeat purchases; combine with MMM to estimate carryover. Report short‑term and long‑term effects separately and set decisions based on both.
What tools do we need?
Start with a registry (even a shared doc), basic power calculators, and BI dashboards. As volume grows, adopt an experimentation platform for randomization, telemetry, diagnostics (SRM), variance reduction, and analysis templates.
How do we prevent “test chaos” across teams?
Create an experimentation council, a backlog tied to strategy, shared templates, and a single repository. Use a light approval path for low‑risk tests and stricter reviews for pricing/promo or partner‑sensitive tests.
What if results are inconclusive?
Don’t over‑interpret. Options: increase duration/sample, test a larger change (higher signal), improve variance reduction, or redirect effort to higher‑leverage hypotheses. Document the null—“no difference at MDE X”—so future teams don’t retest the same variant.
