

1. What Is the A/B and Multivariate Testing Cycle?
The A/B and Multivariate Testing Cycle is a structured, repeatable process for improving performance by running controlled online experiments. In an A/B test, you compare a single variant (B) to a control (A) to measure causal lift on a key outcome. In Multivariate Testing (MVT), you test multiple elements (e.g., headline × image × CTA) simultaneously to estimate both individual effects and interactions. The “cycle” emphasizes that experimentation is not a one-off tactic; it is an operating loop: define hypotheses, design and power the test, execute with guardrails, analyze, decide, scale, and document learnings to inform the next wave.
As a measurement, analytics, and performance management framework, the cycle turns ideas into evidence. It is applicable across marketing (creative, audiences, landing pages), pricing and promotions (depth, fences, thresholds), product/UX (flows, features), retail media timing, sales enablement, and partner programs. Properly run, it produces decision-grade results focused on incremental value (contribution, CLV) and protects economics (pocket price, channel health) while avoiding the pitfalls of correlation and platform-reported attribution alone.
Executives adopt this framework to shorten time-to-learning, reduce risk from large untested changes, and create a compounding growth engine grounded in causal evidence.
2. Origin and Background
Origin: Unknown; business experimentation draws on the scientific method and randomized controlled trials used since the 20th century in medicine and industrial design. A/B testing scaled with the web and mobile in the 2000s as digital telemetry and feature flagging made randomization practical. MVT and factorial designs have roots in statistics (Fisher, Box) and were adapted to digital optimization as tools matured.
Why it was created: Leaders needed fast, credible answers to “what works” when user-level tracking is biased and markets shift quickly. Controlled tests provide causal lift estimates with known uncertainty and enable safe scaling. MVT extends this by answering which combination of elements performs best and where interactions matter.
How it became known: Through product-led tech companies, ecommerce and performance marketing teams, and retail geo-testing traditions. The cycle has been codified in experimentation platforms, analytics playbooks, and consulting practices.
3. How the A/B and Multivariate Testing Cycle Works
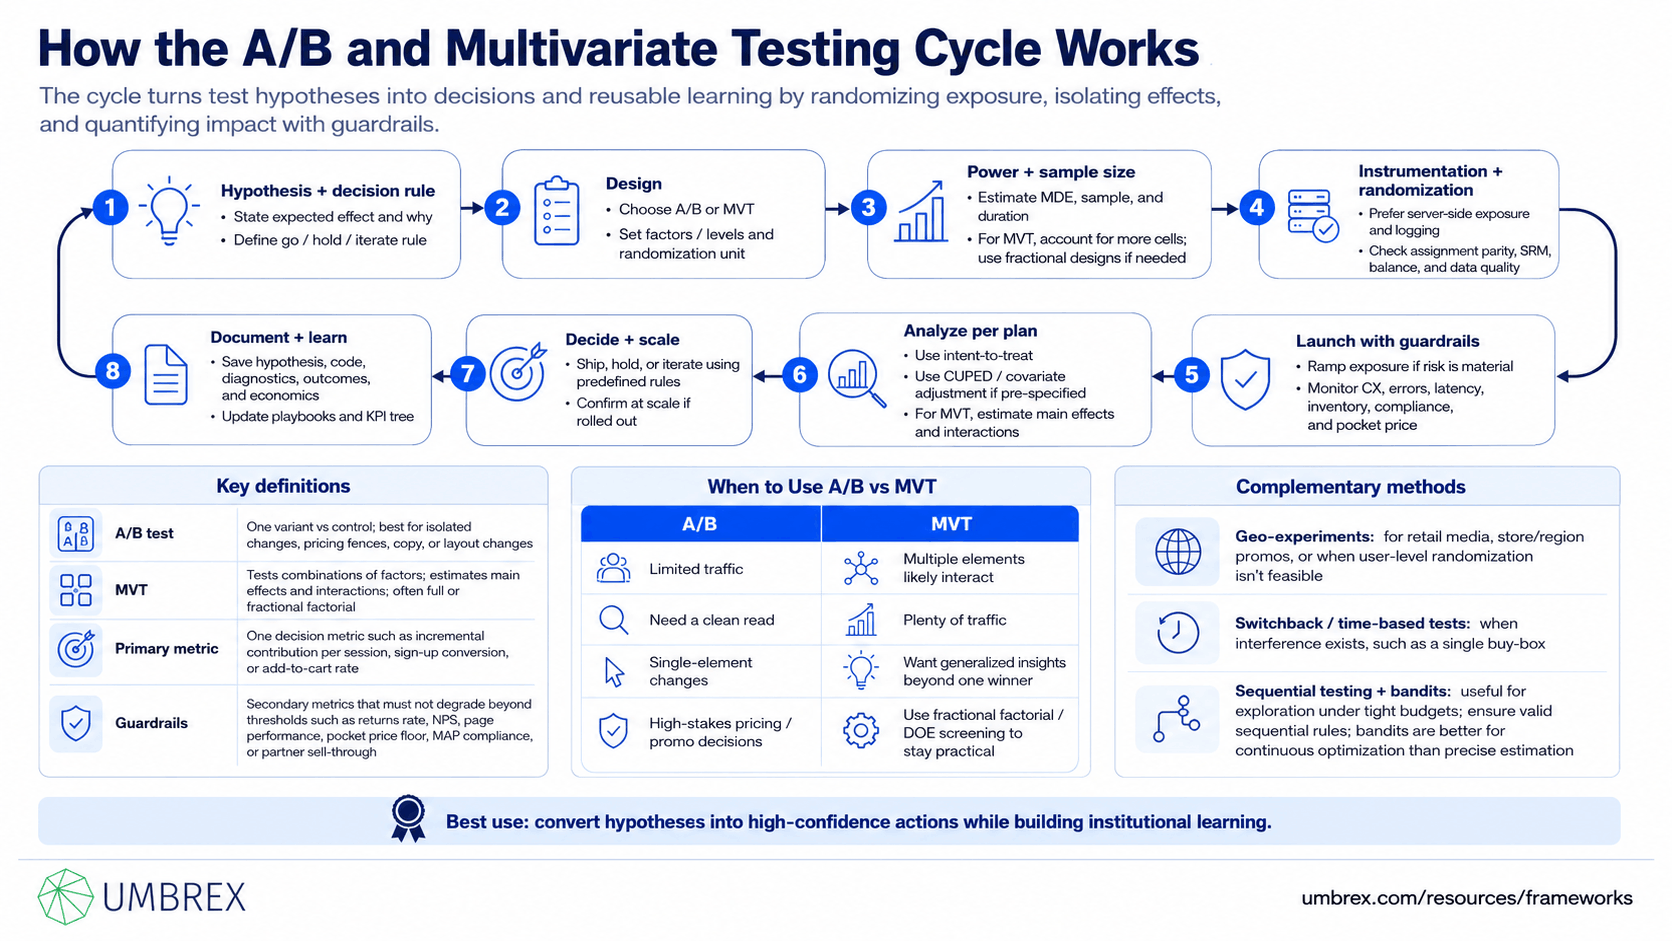
The cycle comprises a set of steps that convert hypotheses into actions and institutional learning. The core logic: randomize exposure, isolate the effect, and quantify impact on business outcomes with guardrails for risk.
Key Definitions
- A/B test: One variant vs control; ideal for isolated changes, pricing fences, copy, or layout adjustments.
- Multivariate Test (MVT): Tests combinations of factors (e.g., 2×3×2 design); estimates main effects and interactions. Often implemented as a full or fractional factorial to manage sample size.
- Primary metric: A single decision metric (e.g., incremental contribution/session, sign-up conversion, add-to-cart rate).
- Guardrails: Secondary metrics that must not degrade beyond thresholds (e.g., returns rate, NPS, page performance, pocket price floor, MAP compliance, partner sell-through).
The Operating Steps
- 1) Hypothesis and decision rule: “If we replace blanket 15% off with a member-only bundle, contribution per session will increase by ≥8% with ≤2% unit loss.” Document a go/hold/iterate rule tied to the primary metric and guardrails.
- 2) Design: Choose A/B vs MVT based on the question. For MVT, determine factors and levels; plan full vs fractional factorial. Select the unit of randomization (user/account/session) to minimize contamination and reflect the decision layer.
- 3) Power and sample size: Based on baseline rate/variance and minimum detectable effect (MDE), estimate sample/time to achieve ≥80% power at your chosen error rate. For MVT, account for additional cells and consider fractional designs to remain feasible.
- 4) Instrumentation and randomization: Implement server-side exposure and logging where possible; verify assignment and event capture parity. Pre-build checks for sample ratio mismatch (SRM), balance, and data quality.
- 5) Launch with guardrails: Ramp exposure (e.g., 5%→25%→50%) if risk is material. Monitor CX, errors, latency, inventory, partner compliance, and pocket price. Freeze variant content unless pre-specified.
- 6) Analyze per plan: Use intent-to-treat analysis; apply variance reduction (e.g., CUPED/covariate adjustment) as pre-specified; for MVT, fit factorial models to estimate main and interaction effects. Report effect sizes with confidence or credible intervals.
- 7) Decide and scale: Apply predefined rules. If you “ship,” roll out with staging and confirm at scale. If “hold,” extend or increase power. If “iterate,” design the next test informed by results (e.g., explore an interaction found in MVT).
- 8) Document and learn: Store hypothesis, design, code, diagnostics, outcomes, and economics in a searchable repository; update playbooks and your KPI tree with sensitivities.
When to Use A/B vs MVT
- A/B: Limited traffic, need a clean read, single-element changes, or high-stakes pricing/promo decisions where simplicity and power are paramount.
- MVT: Multiple elements likely interact (e.g., headline × image × CTA), plenty of traffic, or you want generalized insights (main effects) beyond one winning combo. Consider fractional factorial or DOE screening to keep sample requirements practical.
Methods That Complement the Cycle
- Geo-experiments: For retail media, store/region promos, or when user-level randomization isn’t feasible.
- Switchback/time-based tests: When interference exists (e.g., a single buy-box); alternate variants across time slots.
- Sequential testing and bandits: For exploration under tight budgets, but ensure valid sequential rules and beware of bias; bandits are better for continuous optimization than precise estimation.
4. When to Use the A/B and Multivariate Testing Cycle
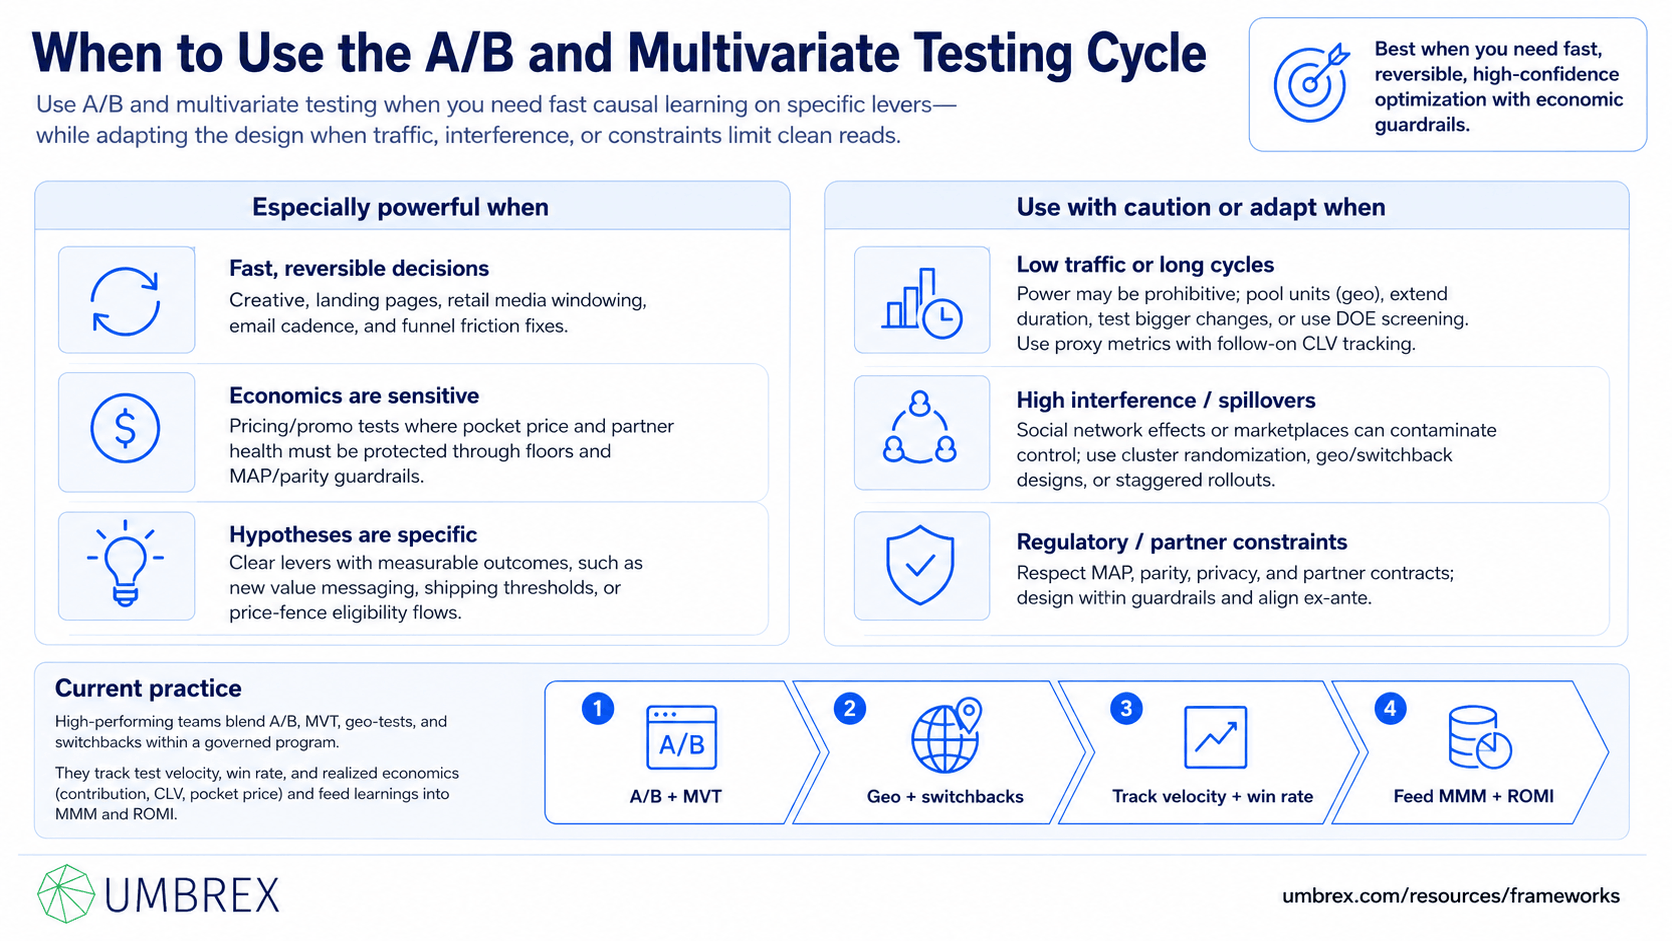
Especially powerful when:
- Fast, reversible decisions: Creative, landing pages, retail media windowing, email cadence, funnel friction fixes.
- Economics are sensitive: Pricing/promo tests where pocket price and partner health must be guarded via floors and MAP/parity.
- Hypotheses are specific: Clear levers with measurable outcomes (e.g., new value messaging, shipping threshold, price fence eligibility flow).
Use with caution or adapt when:
- Low traffic or long cycles: Power may be prohibitive; pool units (geo), extend duration, test bigger changes, or use DOE screening. Use proxy metrics (pipeline) with follow-on CLV tracking.
- High interference/spillovers: Social network effects or marketplaces can contaminate control; use cluster randomization, geo/switchback designs, or staggered rollouts.
- Regulatory/partner constraints: Respect MAP, parity, privacy, and partner contracts; design within guardrails and align ex-ante.
Current practice: High-performing teams blend A/B, MVT, geo-tests, and switchbacks within a governed program that tracks test velocity, win rate, and realized economics (contribution, CLV, pocket price) and feeds results into MMM and ROMI.
5. How to Apply the A/B and Multivariate Testing Cycle: Step-by-Step
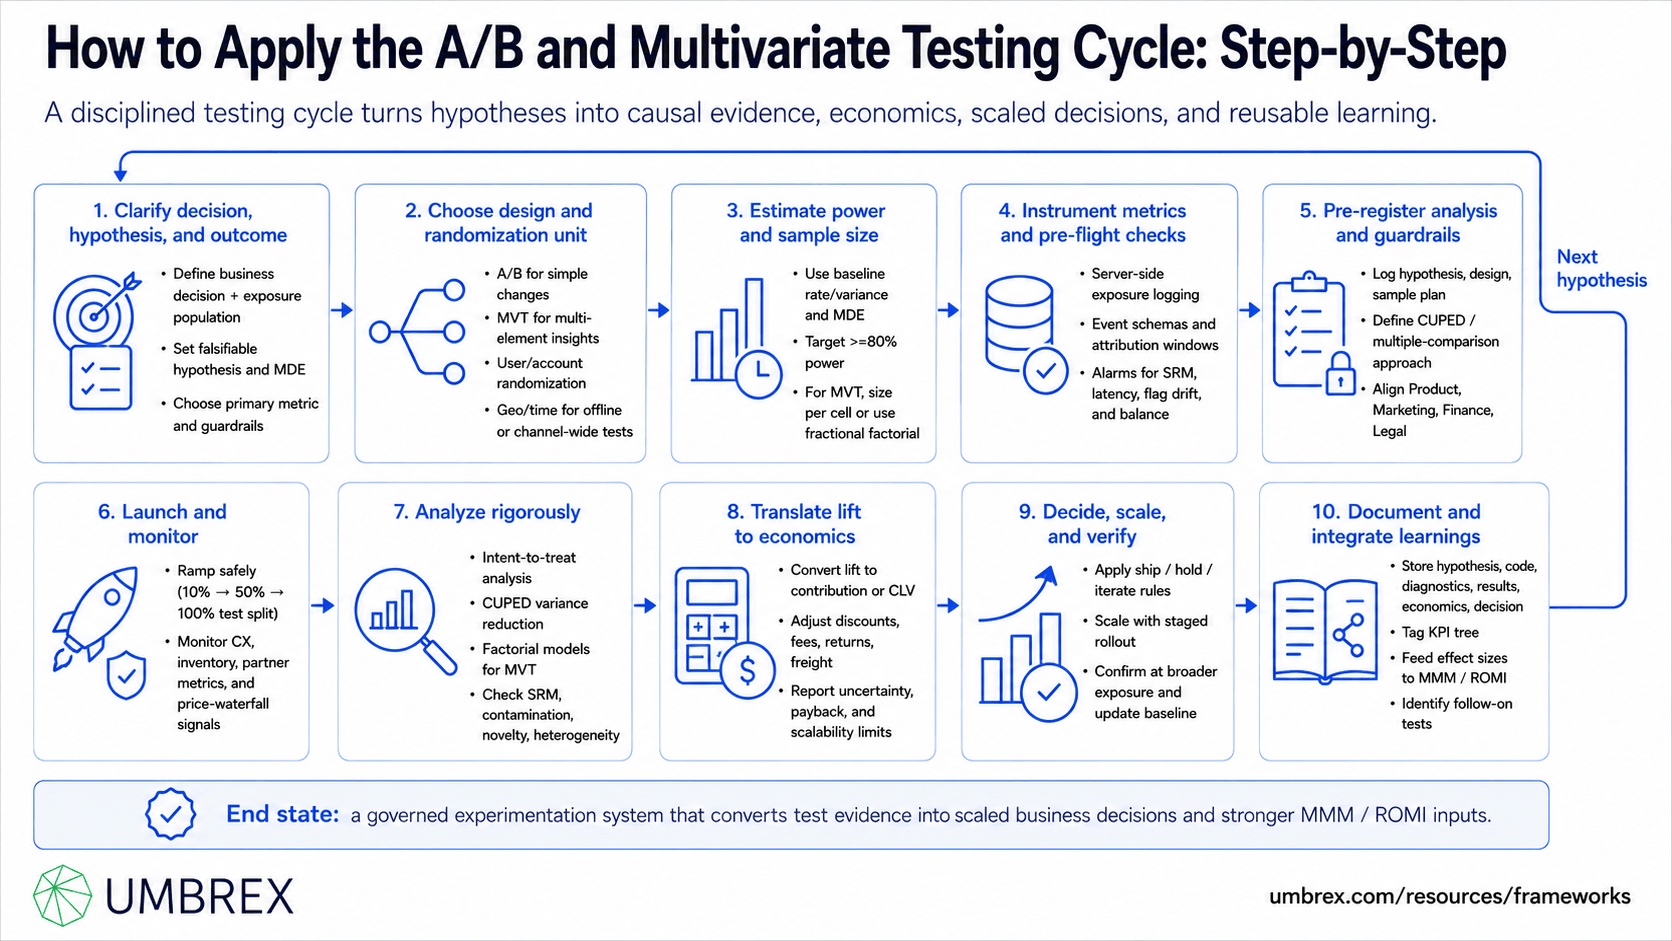
- Clarify the decision, hypothesis, and outcome
State the business decision (e.g., change promo structure), a falsifiable hypothesis (effect size and direction), the primary metric (contribution/session, qualified lead rate, CLV proxy), and guardrails (returns ≤ baseline, pocket price ≥ floor, CX performance, partner compliance). Define the exposure population and exclusion criteria (e.g., existing subscribers).
- Choose design and randomization unit
Pick A/B for simple changes or low-traffic contexts; MVT for multi-element insights. Select user/account-level randomization to avoid cross-exposure; use session-level only for minor UI tests without persistent effects. For channel-wide or offline, plan geo or time-based designs.
- Estimate power and sample size
Use baseline rates/variance to compute the sample/time needed to detect your MDE with ≥80% power at α=0.05 (or your standard). For MVT, calculate per-cell requirements; use fractional factorial (e.g., Taguchi designs) if full factorial is infeasible. Account for novelty and seasonality in duration.
- Instrument metrics and pre-flight checks
Implement server-side exposure logging; define event schemas; align time zones and attribution windows. Build alarms for SRM, data latency, and feature flag drift. Validate randomization balance on key covariates (traffic source, device, geography).
- Pre-register analysis and guardrails
Record in a test registry: hypothesis, design, sample plan, primary/secondary metrics, variance-reduction plan (e.g., CUPED), multiple-comparison control (for MVT: control FWER/FDR), interim looks (if allowed by sequential methods), and decision thresholds. Align stakeholders (Product, Marketing, Finance, Legal/Privacy).
- Launch and monitor
Ramp exposure safely (e.g., 10%→50%→100% test split). Watch CX (latency, error rates), inventory, partner metrics (MAP/buy-box), and price waterfall signals (discounts, fees, returns). Pause if guardrails breach.
- Analyze rigorously
Run intent-to-treat analyses; adjust variance with pre-specified covariates (CUPED) to improve power. For MVT, fit factorial models to estimate main effects and interactions; visualize effect plots to detect synergistic combinations. Check diagnostics: SRM, contamination, novelty decay, heterogeneity by segment.
- Translate lift to economics
Convert outcome lift to contribution or CLV, adjusting for the price waterfall (discounts, rebates, commissions/fees, returns, freight, payment terms). Report effect sizes with uncertainty intervals, payback periods, and scalability constraints (saturation, inventory, partner capacity).
- Decide, scale, and verify
Apply pre-defined decision rules to ship/hold/iterate. Scale with staged rollouts and confirm effects at broader exposure; watch for novelty fade or capacity constraints. Codify the change (feature flag on), and update playbooks/guardrails if this becomes a new baseline.
- Document and integrate learnings
Store details (hypothesis, design, code, diagnostics, results, economics, decision) in a searchable repository. Tag learnings in your KPI tree (which nodes moved) and feed effect sizes to MMM/ROMI. Identify follow-on tests—e.g., turn an MVT-favored combination into a new A/B vs refined control for confirmation.
6. Example: A/B and MVT in Action
Company: “SummitSleep,” a $350M omnichannel mattress brand (D2C, marketplaces, and national retailers).
Problem: CAC had risen; the site leaned on 15% blanket coupons that leaked to marketplaces; retail partners complained about undercutting. Pocket price was down 130 bps YoY. The team needed to protect contribution while sustaining growth.
Tests:
- A/B—Promo structure (D2C): Control (15% sitewide) vs Variant (member-only bundle: free pillows + 5% off; single-use codes). Primary metric: contribution/session; guardrails: conversion, returns, CX, pocket price floor.
- MVT—PDP communication: 2×3×2 factorial: value frame (sleep quality vs savings) × hero image (product-only vs lifestyle vs feature callouts) × CTA wording (Shop Now vs Get Better Sleep). Primary metric: add-to-cart rate; guardrails: page performance, scroll depth, exit rate.
- Geo switchback—Retail promo depth: Alternate weeks at 20% vs 15% discount with retail media bursts; primary: sell-through; guardrails: retailer margin, buy-box, MAP compliance.
Results:
- A/B: Contribution/session +11.2% (95% CI: +7.5% to +14.9%); conversion −0.8 pts (ns); returns unchanged; pocket price +100 bps; member sign-ups +21%.
- MVT: Main effects—sleep-quality framing (+7% add-to-cart) and feature-callout hero (+5%). Interaction positive: sleep-quality frame × feature-callout (+3% over additive expectation). Final combo improved add-to-cart +12% with negligible perf impact.
- Geo switchback: 15% depth with retail media yielded statistically similar sell-through (−1.5%, ns) vs 20% depth but pocket price +90 bps; retailer feedback positive on margin stability.
Decisions: Scaled member-only bundle and single-use codes; set promo depth cap at 15% with synchronized retail media; deployed new PDP combo from MVT as the default (validated via confirmation A/B). Next: test shipping threshold messaging with stratified A/B. Two quarters later, pocket price +120 bps, blended ROMI up from 1.22 to 1.51, and retailer satisfaction improved.
7. Strengths and Limitations
Strengths
- Causal, fast learning: Produces decision-grade evidence and reduces reliance on correlation or anecdote.
- Economic focus: When tied to contribution/CLV and pocket price, tests drive profitable growth, not just top-line lift.
- Scalable operating model: A cycle of hypothesis → test → learn → scale creates compounding capability.
- MVT insights: Factorial designs reveal which elements matter and how they interact—informing design systems, not just “one winner.”
Limitations
- Power constraints: Low traffic or long cycles make tests slow or inconclusive; MVT magnifies sample needs.
- Interference risk: Marketplaces, social networks, and word-of-mouth can contaminate exposure; requires careful design or alternative methods.
- Local validity: A win in one context may not generalize; follow-on tests and rollout verification are required.
- Operational overhead: Requires instrumentation, governance, and cultural adoption; parallel tests can interact without a registry.
8. Common Pitfalls (and How to Avoid Them)
- Peeking/p-hacking
What goes wrong: Early looks and unplanned cuts inflate false positives.
How to avoid: Pre-register analysis; use fixed horizons or valid sequential methods; report uncertainty bands. - Under-powered tests
What goes wrong: Inconclusive reads, wasted cycles.
How to avoid: Plan MDE; use variance reduction; pool units (geo), test larger effects, or run DOE screening before MVT. - Sample ratio mismatch (SRM)
What goes wrong: Broken randomization skews results.
How to avoid: Monitor SRM and randomization balance continuously; pause and fix before reading. - Contamination/interference
What goes wrong: Users see multiple variants; spillovers bias estimates.
How to avoid: Randomize at user/account, switchback, or cluster; measure cross-exposure; separate traffic streams. - Wrong success metric
What goes wrong: Optimize clicks or revenue while margin erodes.
How to avoid: Use contribution/CLV as primary; include price waterfall adjustments and partner guardrails. - Ignoring multiple comparisons (MVT)
What goes wrong: False discoveries when many factors/levels are tested.
How to avoid: Pre-specify factors, control FWER/FDR, or emphasize effect sizes and replication over p-values alone. - Novelty and learning effects
What goes wrong: Early spikes fade; teams over-ship.
How to avoid: Run long enough to pass novelty; re-check post-rollout (holdback cells or staggered ramps). - Mid-test changes
What goes wrong: Moving targets invalidate inference.
How to avoid: Freeze variants or restart; maintain change logs and versioning. - No documentation
What goes wrong: Repeated mistakes, lost learnings.
How to avoid: Maintain a registry and repository; standardize templates; tag results to playbooks and KPI trees.
9. How the A/B and Multivariate Testing Cycle Relates to Other Frameworks
- Test-and-Learn Experimentation Framework: The broader governance and operating system; A/B and MVT are core methods within it for micro-decisions.
- ROMI: Experiments provide lift that converts to contribution/CLV ROMI and payback; they de-risk reallocations and set guardrails.
- Marketing Mix Modeling (MMM): Use experimental effects to calibrate MMM coefficients; MMM scales learnings across time, channels, and accounts for price/promo and diminishing returns.
- Attribution Modeling: Attribution guides weekly optimization; experiments validate incrementality and correct bias (e.g., affiliates, branded search).
- Marketing KPI Tree: Tests move nodes (conversion, AOV, price realization); record elasticities to direct future work.
- Brand Tracking Funnel: Tests can shift consideration or preference (messaging/creative) and validate funnel-to-revenue links.
- Price Waterfall & Promotional Mechanics: Pricing/promo experiments must be read net of discounts, fees, returns, and partner terms—with MAP/parity guardrails.
- SOV–SOM: A/B creative/format tests confirm whether increased “voice” translates into brand and sales movement before committing to sustained ESOV.
10. Key Takeaways
- A/B and Multivariate Testing, run as a disciplined cycle, deliver causal answers fast and safely—turning ideas into measurable value.
- Select A/B for simple, high-power reads; use MVT when multiple elements likely interact and traffic supports factorial designs.
- Pre-register hypotheses, metrics, power, and guardrails; monitor SRM and contamination; analyze with variance reduction and appropriate multiple-test controls.
- Measure what matters: contribution/CLV and pocket price, with CX and partner guardrails—not just clicks or attributed revenue.
- Institutionalize learning with a registry and repository; feed results into MMM, ROMI, attribution, and KPI trees to scale impact.
11. FAQs About the A/B and Multivariate Testing Cycle
How do I choose between A/B and MVT?
Use A/B when traffic is limited, the change is isolated, or you need a clean, high-power read (e.g., pricing fence). Use MVT when multiple elements may interact and you want generalized insights; manage sample needs with fractional factorial designs and focus on main effects.
What’s the minimum traffic needed?
It depends on baseline rate/variance and the effect size you care about (MDE). As a rule, plan for ≥80% power at α=0.05. If you can’t reach power in a reasonable time, test larger changes, pool units (geo), apply variance reduction (CUPED), or run DOE screening before MVT.
Frequentist vs Bayesian—does it matter?
Both can work if pre-specified and governed. Frequentist methods are standard and simple; Bayesian analysis provides intuitive credible intervals and can support monitored tests with proper stopping rules. The bigger risk is p-hacking, not which paradigm you choose.
How do we prevent coupon leakage or partner undercutting during promo tests?
Use single-use, account-bound codes; fence offers (member-only); coordinate with retail media timing; enforce MAP/parity; and evaluate tests on pocket price and partner metrics, not just order volume.
How do we handle multiple comparisons in MVT?
Pre-specify factors/levels; focus on main effects; control FWER (e.g., Bonferroni/Holm) or FDR (Benjamini–Hochberg) for interactions; emphasize effect sizes and replication over p-values alone.
Can we run tests in marketplaces or with retail partners?
Yes—use geo or switchback designs, align with partner calendars, and respect MAP/parity. Monitor buy-box, ratings, and retailer margin as guardrails; analyze sell-through and pocket price, not only orders.
What if results are inconclusive?
Don’t over-interpret. Options: extend duration, increase traffic, reduce MDE by variance reduction, test a larger change, or redirect effort. Document the null (“no effect ≥X%”) to prevent retesting the same idea.
How do we incorporate long-term effects?
Track cohorts for retention/CLV and brand outcomes (consideration/preference) where relevant; run follow-up analyses. Use MMM to estimate carryover and include long-run ROMI alongside short-run results in decisions.
