

1. What Is the RATER Service Quality Model?
The RATER Service Quality Model is a practical framework for diagnosing and improving service quality across five dimensions that shape customer perceptions: Reliability, Assurance, Tangibles, Empathy, and Responsiveness. Rather than treating “service quality” as a vague idea, RATER breaks it into concrete components you can measure, manage, and improve.
Within customer, service, CRM, and CX work, RATER functions as a shared language for operations, frontline teams, and leadership. It helps organizations identify where service is strong, where it falls short, and which fixes will meaningfully improve customer satisfaction, loyalty, and cost-to-serve. You can use RATER on its own as a performance lens, or pair it with an “expectations vs. perceptions” survey design (as in SERVQUAL) to quantify gaps.
Consultants and executives use RATER widely because it is simple, portable across industries, and immediately operational. Each dimension translates directly into behaviors, standards, and investments—making it an effective bridge between strategy and day-to-day service delivery.
2. Origin and Background
RATER is derived from the SERVQUAL research program developed by A. Parasuraman, Valarie A. Zeithaml, and Leonard L. Berry in the 1980s. SERVQUAL introduced five core dimensions of service quality that later became commonly remembered as the RATER acronym: Reliability, Assurance, Tangibles, Empathy, and Responsiveness.
Origin of the acronym: Unknown; in use since at least the 1990s. The RATER label was popularized through services marketing textbooks, business schools, and consulting practice as a mnemonic to make SERVQUAL’s dimensions easier to communicate and operationalize.
Why it was created: Organizations needed a disciplined way to define, measure, and improve the elusive concept of “service quality.” RATER simplified the construct into five actionable dimensions and a surveyable structure that reveals where expectations and delivery diverge—so teams can prioritize the fixes that matter most.
3. How the RATER Model Works
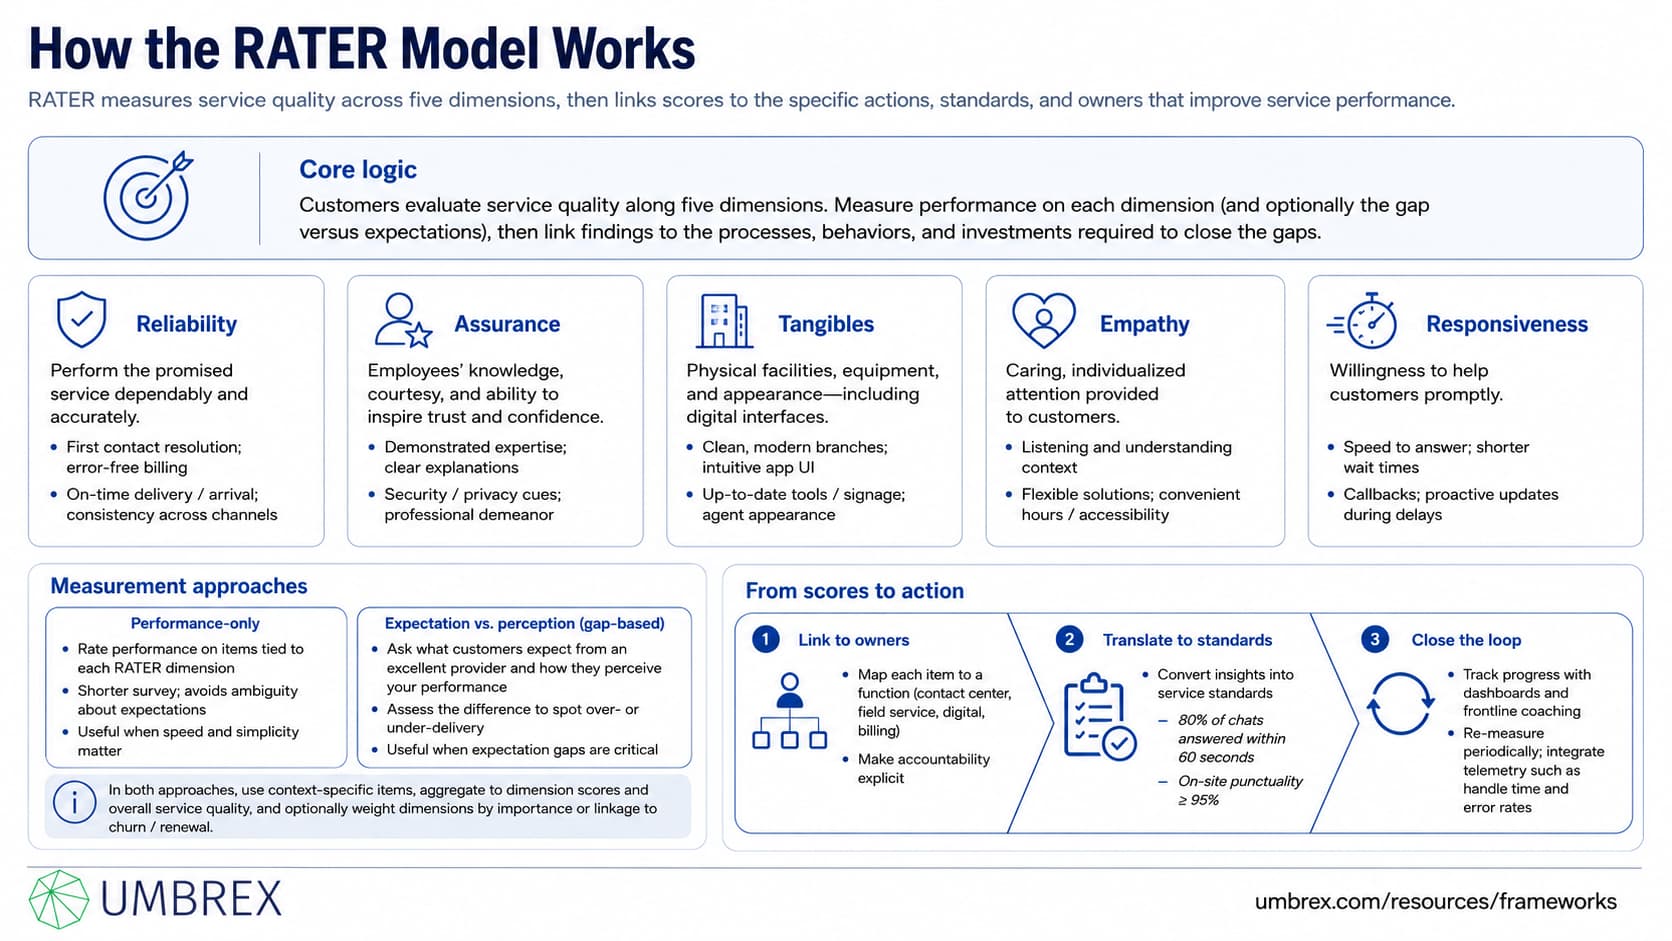
RATER’s core logic is straightforward: customers evaluate service quality along five dimensions. You measure performance on each dimension (and, optionally, the gap versus expectations), then link findings to specific processes, behaviors, and investments to close the gaps.
The five RATER dimensions (spelled out)
- Reliability: The ability to perform the promised service dependably and accurately. Examples: first contact resolution, error-free billing, on-time delivery or appointment arrival, consistency across channels.
- Assurance: Employees’ knowledge, courtesy, and ability to inspire trust and confidence. Examples: demonstrated expertise, clear explanations, security and privacy cues, professional demeanor.
- Tangibles: Physical facilities, equipment, and appearance—including digital interfaces. Examples: clean and modern branches, intuitive app UI, up-to-date tools and signage, agent appearance.
- Empathy: Caring, individualized attention provided to customers. Examples: listening, understanding context, flexible solutions for special cases, convenient hours and accessibility.
- Responsiveness: Willingness to help customers promptly. Examples: speed to answer, wait times, callbacks, proactive updates during delays or outages.
Measurement approaches
- Performance-only: Ask customers to rate your performance on items tied to each RATER dimension. This reduces survey length and avoids ambiguity about “expectations.”
- Expectation vs. perception (gap-based): Ask customers what they expect from an excellent provider and how they perceive your performance, then assess the difference. This highlights where you over- or under-deliver relative to expectations.
In both approaches, items should be specific to your context (e.g., “The technician arrived within the promised window” for Reliability; “The agent explained the resolution clearly” for Assurance). Aggregate item scores into dimension scores and overall service quality. Optionally, weight dimensions by importance derived from customer ratings or statistical linkage to outcomes like churn or renewal.
From scores to action
- Link to owners: Map each item to a function (contact center, field service, digital, billing) so responsibility for improvements is clear.
- Translate to standards: Convert insights into service standards (e.g., “80% of chats answered within 60 seconds,” “On-site punctuality ≥ 95%”).
- Close the loop: Track progress with dashboards, coach frontline behaviors, and re-measure periodically. Integrate operational telemetry (e.g., handle time, error rates) for a complete view.
4. When to Use the RATER Model
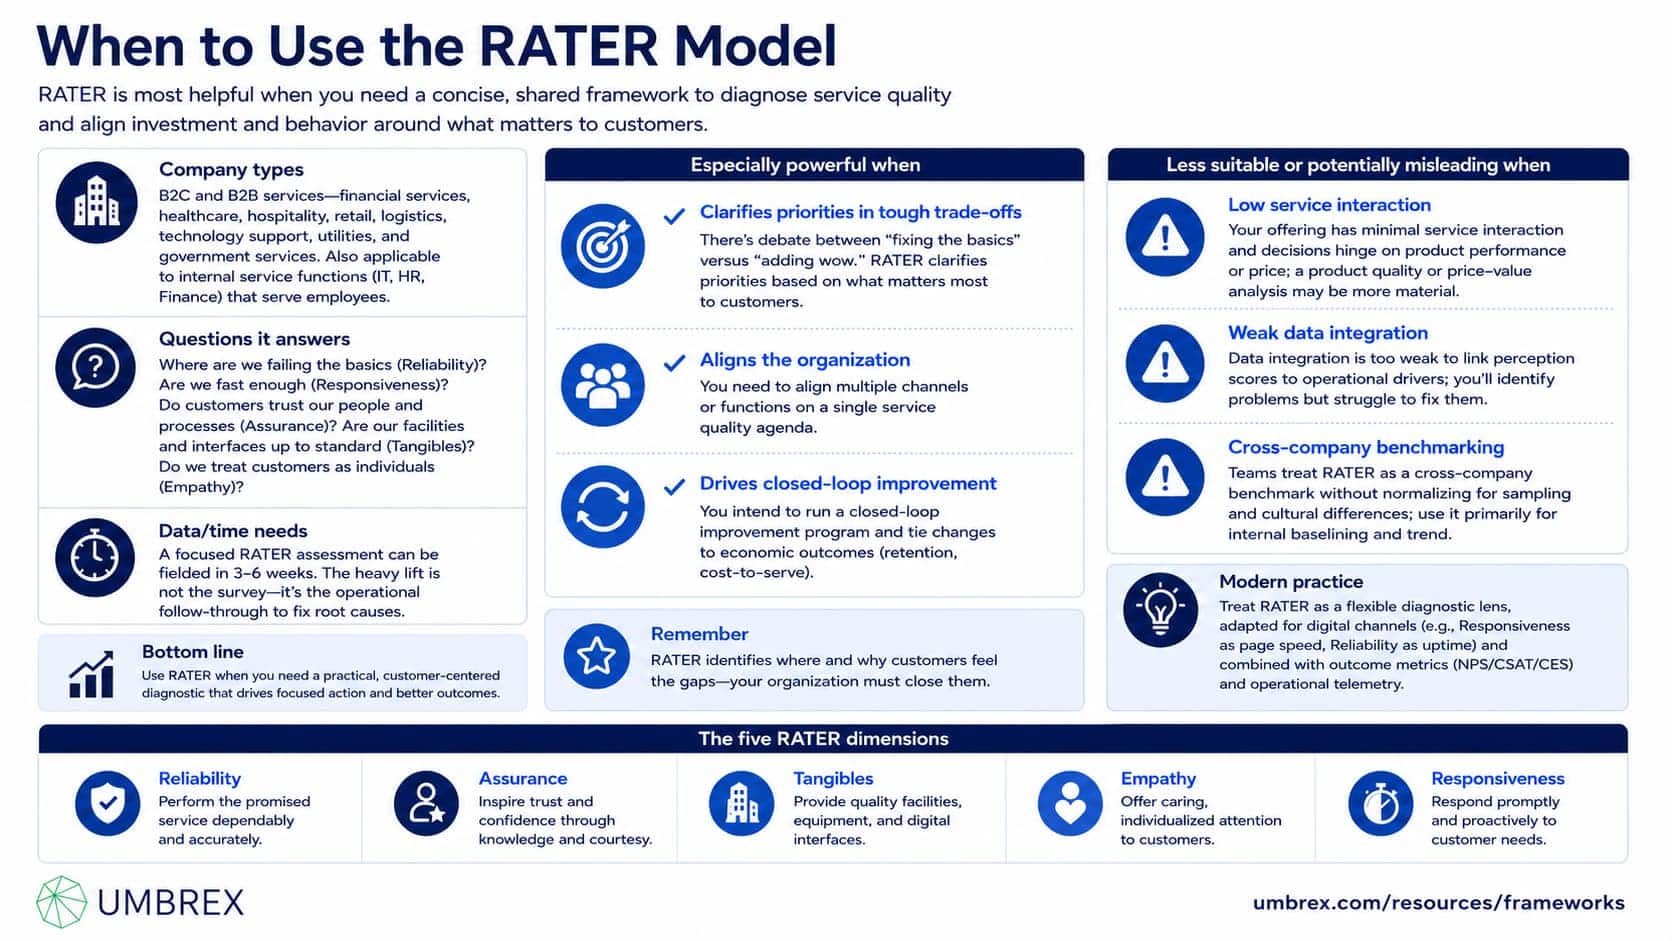
RATER is most helpful when you need a concise, shared framework to diagnose service quality and align investment and behavior around what matters to customers.
- Company types: B2C and B2B services—financial services, healthcare, hospitality, retail, logistics, technology support, utilities, and government services. Also applicable to internal service functions (IT, HR, Finance) that serve employees.
- Questions it answers: Where are we failing the basics (Reliability)? Are we fast enough (Responsiveness)? Do customers trust our people and processes (Assurance)? Are our facilities and interfaces up to standard (Tangibles)? Do we treat customers as individuals (Empathy)?
- Data/time needs: A focused RATER assessment can be fielded in 3–6 weeks. The heavy lift is not the survey—it’s the operational follow-through to fix root causes.
Especially powerful when:
- There’s debate between “fixing the basics” versus “adding wow.” RATER clarifies priorities.
- You need to align multiple channels or functions on a single service quality agenda.
- You intend to run a closed-loop improvement program and tie changes to economic outcomes (retention, cost-to-serve).
Less suitable or potentially misleading when:
- Your offering has minimal service interaction and decisions hinge on product performance or price; a product quality or price-value analysis may be more material.
- Data integration is too weak to link perception scores to operational drivers; you’ll identify problems but struggle to fix them.
- Teams treat RATER as a cross-company benchmark without normalizing for sampling and cultural differences; use it primarily for internal baselining and trend.
Modern practice treats RATER as a flexible diagnostic lens, adapted for digital channels (e.g., Responsiveness as page speed, Reliability as uptime) and combined with outcome metrics (NPS/CSAT/CES) and operational telemetry.
5. How to Apply the RATER Model: Step-by-Step
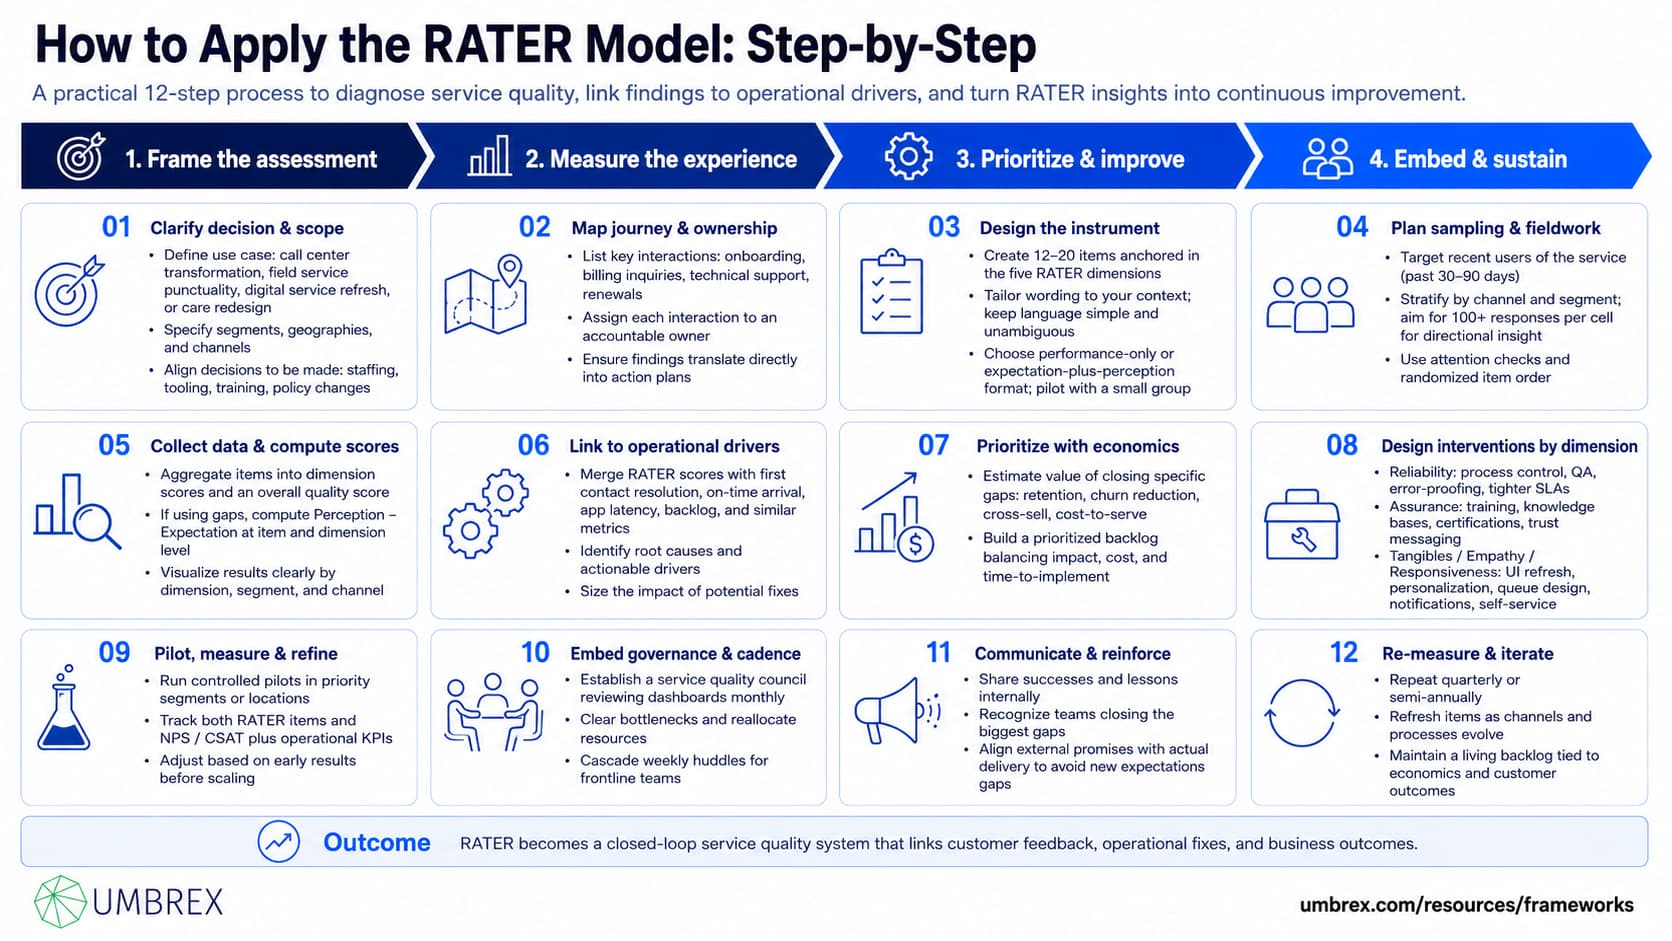
- Clarify the decision and scope
Define what the assessment will inform: a call center transformation, field service punctuality program, digital service refresh, or end-to-end customer care redesign. Specify segments, geographies, and channels. Align on the decisions you’ll make (e.g., staffing model, tooling, training, policy changes).
- Map the service journey and ownership
List key interactions (e.g., onboarding, billing inquiries, technical support, renewals). Assign each to an accountable owner so that findings translate directly into action plans.
- Design the measurement instrument
Create 12–20 items anchored in the five RATER dimensions and tailored to your context. Examples:
– Reliability: “Issue resolved correctly the first time,” “Deliveries arrive on the promised date.”
– Assurance: “Agent demonstrated expertise,” “I felt my data were secure.”
– Tangibles: “App is easy to navigate,” “Facilities were clean and modern.”
– Empathy: “Representative understood my situation,” “Support accommodated my schedule.”
– Responsiveness: “Wait time was acceptable,” “I received timely updates on progress.”
Choose performance-only or expectation-plus-perception format. Keep language simple and unambiguous; pilot with a small group to ensure clarity.
- Plan sampling and fieldwork
Target recent users of the service (past 30–90 days). Stratify by channel and segment; aim for sufficient responses per cell (e.g., 100+ for directional insight). Use attention checks and randomized item order to improve data quality.
- Collect data and compute scores
Aggregate item responses into dimension scores and an overall service quality score. If you collected expectations and perceptions, compute gaps (Perception minus Expectation) at the item and dimension level.
- Link to operational drivers
Merge RATER results with operational metrics (e.g., first contact resolution, on-time arrival, app latency, backlog) to identify root causes. This makes findings actionable and helps size the impact of potential fixes.
- Prioritize with economics
Estimate the value of closing specific gaps: impact on retention, churn reduction, cross-sell, and cost-to-serve (e.g., fewer repeat contacts). Build a prioritized backlog balancing impact, cost, and time-to-implement.
- Design interventions by dimension
– Reliability: process control, checklists, quality assurance, error-proofing, standard work; tighten SLAs and escalation paths.
– Assurance: training on expertise cues, updated knowledge bases, certifications, trust and security messaging.
– Tangibles: UI/UX refresh, signage and facility updates, tool modernization, accessibility improvements.
– Empathy: coaching on listening and personalization, playbooks for vulnerable or high-value segments, flexible policies.
– Responsiveness: staffing models, queue design, callback promises, proactive notifications, self-service enhancements.
- Pilot, measure, and refine
Run controlled pilots in priority segments or locations. Track both perception metrics (RATER items, NPS/CSAT) and operational KPIs. Adjust based on early results before scaling.
- Embed governance and cadence
Establish a service quality council that reviews RATER dashboards monthly, clears bottlenecks, and reallocates resources. Cascade weekly huddles for frontline teams to share wins and address recurring issues.
- Communicate and reinforce
Share successes and lessons internally; recognize teams closing the biggest gaps. Align external promises with actual delivery to avoid creating new expectations gaps.
- Re-measure and iterate
Repeat the assessment quarterly or semi-annually. Refresh items as channels and processes evolve. Maintain a living backlog tied to economics and customer outcomes.
6. Example: RATER in Action
Context: “MediWell Clinics,” a $900M multi-state outpatient healthcare provider, faced rising complaints about appointment scheduling, long waits, and inconsistent staff communication. Patient leakage to competitors was increasing, and the CEO wanted a fact-based plan to elevate service quality.
Approach: The team deployed a RATER assessment across scheduling, check-in, consultation, and follow-up. They used a performance-only survey (15 items) aligned to RATER and captured operational data (no-show rates, time-to-appointment, average wait time, call abandon rates).
Findings:
- Reliability: Low first-time accuracy in appointment type and duration led to frequent rescheduling (poor Reliability). Error-prone insurance coding increased billing disputes.
- Responsiveness: Long call center wait times during morning peaks; in-clinic wait averages of 29 minutes with no proactive updates.
- Assurance: Variability in clinicians’ explanations of treatment plans; patients reported uncertainty about next steps.
- Tangibles: Digital check-in flow was confusing on mobile; signage in clinics was outdated.
- Empathy: Patients with chronic conditions felt rushed; limited accommodation for mobility-impaired visitors.
Linking to economics showed that clinics in the bottom quartile on Reliability and Responsiveness had 1.7x higher churn (patients choosing competitors) and higher rework costs.
Actions:
- Introduced an appointment “reason and prep” checklist in the scheduling system; built guardrails to match slot duration with visit type (Reliability).
- Added a staffing surge plan and callback option for peak hours; deployed proactive SMS updates for waits exceeding 15 minutes (Responsiveness).
- Created standardized “teach-back” scripts and after-visit summaries to reinforce care plans (Assurance).
- Redesigned mobile check-in screens; refreshed signage; upgraded waiting room seating with accessibility in mind (Tangibles).
- Flagged chronic and mobility-impaired patients in the system for extended appointment slots and priority seating (Empathy).
Outcomes (three months): Call abandon rate fell from 18% to 7%; average in-clinic waits dropped to 18 minutes; billing dispute rate decreased 24%. Patient-reported Reliability and Responsiveness scores rose by 0.6 and 0.7 points (on a 5-point scale). Quarterly retention improved by 140 bps in pilot clinics, and rework costs declined. The board approved scaling initiatives system-wide.
7. Strengths and Limitations
Strengths
- Clarity: Five plain-English dimensions create a common language across functions and levels.
- Actionability: Items map directly to processes, standards, and frontline behaviors.
- Flexibility: Works with performance-only or gap-based measurement; adaptable to digital and physical channels.
- Comparability over time: Repeatable instrument suited for baselining and tracking progress.
- Economic linkage: Findings connect to drivers of churn, retention, and cost-to-serve.
Limitations
- Ambiguity in expectations: If you use gap-based surveys, “expectations” can be interpreted inconsistently by respondents.
- Potential oversimplification: Five dimensions can mask nuance or interdependencies between processes.
- Benchmarking pitfalls: Cross-company comparisons are fragile due to sampling and cultural differences; prioritize internal trend analysis.
- Survey burden: Long instruments create fatigue; shorter versions sacrifice diagnostic depth.
8. Common Pitfalls (and How to Avoid Them)
- Using generic items that don’t fit your context
What goes wrong: Vague questions yield vague guidance.
How to avoid: Tailor items to your processes and channels while preserving the five dimensions.
- Chasing scores without fixing root causes
What goes wrong: Cosmetic changes improve perception briefly but don’t address failures.
How to avoid: Pair RATER with operational diagnostics (process maps, call listening, QA) and tie initiatives to measurable drivers.
- Overinvesting in Tangibles while basics lag
What goes wrong: Shiny interfaces alongside unreliable service.
How to avoid: Prioritize Reliability and Responsiveness before aesthetic improvements.
- Ignoring segment and channel differences
What goes wrong: Averages hide critical pain points (e.g., high-value accounts, vulnerable users).
How to avoid: Cut results by segment and channel; build targeted plays for high-impact cohorts.
- Poor linkage to ownership
What goes wrong: Insights with no accountable owner stall.
How to avoid: Map each item to a specific function and leader; establish a backlog with deadlines.
- One-and-done measurement
What goes wrong: Momentum fades; improvements regress.
How to avoid: Re-measure on a cadence and integrate RATER into regular operating reviews.
9. How RATER Relates to Other Frameworks
- SERVQUAL: RATER is the mnemonic for SERVQUAL’s five dimensions. Use SERVQUAL’s gap logic (expectations vs. perceptions) when you want explicit insight into over/under-delivery; use performance-only when simplicity and response rates are paramount.
- NPS, CSAT, CES: These provide headline outcomes (advocacy, satisfaction, effort). Use RATER to diagnose which aspects of service drive those outcomes and where to invest.
- Customer Journey Mapping and Service Blueprinting: RATER identifies which dimensions are weak; journey maps and blueprints show where in the journey and which backstage processes to fix.
- Kano Model: Kano distinguishes basics, performance drivers, and delighters. RATER ensures basics (Reliability, Responsiveness) are solid before adding delighters that risk backfiring if the core is broken.
- Lean Six Sigma and COPC: Once RATER pinpoints gaps, process improvement and operational standards provide methods and targets to close them.
- CLV and churn modeling: Use these to quantify the financial payoff of closing RATER gaps and to prioritize initiatives across segments.
Typical flow: Track outcomes (NPS/CSAT/CES) → Diagnose with RATER by dimension → Use journey maps/blueprints to design fixes → Apply Lean/Six Sigma to implement → Validate ROI via CLV and churn.
10. Key Takeaways
- RATER breaks service quality into five actionable dimensions—Reliability, Assurance, Tangibles, Empathy, Responsiveness—creating a common language for improvement.
- Measure performance (and optionally the expectation–perception gap), then link findings to operational drivers and accountable owners.
- Fix basics first: prioritize Reliability and Responsiveness before investing in aesthetics or “wow” moments.
- Adapt items to your context, segment results, and re-measure regularly; use RATER as a management system, not a one-off survey.
- Combine RATER with journey mapping, service blueprinting, and outcome metrics (NPS/CSAT/CES) to turn insight into ROI-positive change.
11. FAQs About the RATER Service Quality Model
Is RATER the same as SERVQUAL?
RATER is the mnemonic for SERVQUAL’s five dimensions. SERVQUAL adds a specific gap-based measurement method (expectations and perceptions). Many teams use the RATER dimensions with either performance-only or gap-based surveys depending on context and survey length constraints.
How many questions do we need to assess RATER well?
A practical range is 12–20 items tailored to your channels and processes, with 2–5 items per dimension. Keep it short enough to avoid fatigue while preserving diagnostic coverage; pilot and refine wording for clarity.
Can small or early-stage companies use RATER?
Yes. Start lean with a brief performance-only survey, cut results by channel/segment, and focus on a handful of high-impact fixes (often Reliability and Responsiveness). As you scale, add operational telemetry and governance.
How long does a RATER project take?
A focused effort can be designed and fielded in 3–6 weeks, with another 2–4 weeks to translate findings into an actionable backlog. The larger timeline driver is implementing operational changes and measuring impact.
How should we weight the five dimensions?
If all dimensions are not equally important for your customers, derive weights empirically—via customer-stated importance or regression linking RATER scores to outcomes like churn or NPS. Apply weights transparently and revisit them periodically as your mix of journeys and segments evolves.
