

1. What Is the PIE Testing Framework (Potential, Importance, Ease)?
The PIE Testing Framework is a lightweight, structured method for prioritizing conversion and growth experiments. PIE stands for Potential, Importance, and Ease. You score each candidate test or change on these three dimensions—typically on a 1–10 scale—then rank by the combined score to decide what to run first.
In digital, ecommerce, growth, and product contexts, PIE helps teams allocate scarce experimentation capacity to the highest-value, lowest-regret bets. It turns subjective debate (“this page feels broken”) into a quick, repeatable scoring exercise grounded in data, business value, and implementation complexity. Its simplicity makes it a favorite for CRO (conversion rate optimization) programs, landing page and funnel tests, merchandising and pricing experiments, and in-app UX changes.
PIE is intentionally pragmatic. It won’t replace full business casing or detailed engineering estimation, but it will give you a disciplined “fast lane” to keep the experimentation flywheel turning while protecting time for bigger strategic bets.
2. Origin and Background
The PIE Framework was popularized in the conversion optimization field by Chris Goward and the WiderFunnel team in the early 2010s, including in Goward’s book “You Should Test That!” (2012). It emerged from the need to tame long testing backlogs with a simple, communicable rubric that non-technical stakeholders could apply consistently.
Why it was created: CRO programs often drown in ideas, most of which lack clear evidence, comparable effort estimates, or a shared sense of business impact. PIE gave teams a common yardstick—Potential (how much that area could improve), Importance (how much traffic/value it represents), and Ease (how hard it is to execute)—so they could move quickly without losing the plot.
How it spread: Through CRO consultancies, in-house growth teams, and experimentation platforms’ playbooks. It has since been adapted beyond web pages to email campaigns, onboarding flows, app features, pricing/packaging experiments, and merchandising tests.
3. How the PIE Framework Works
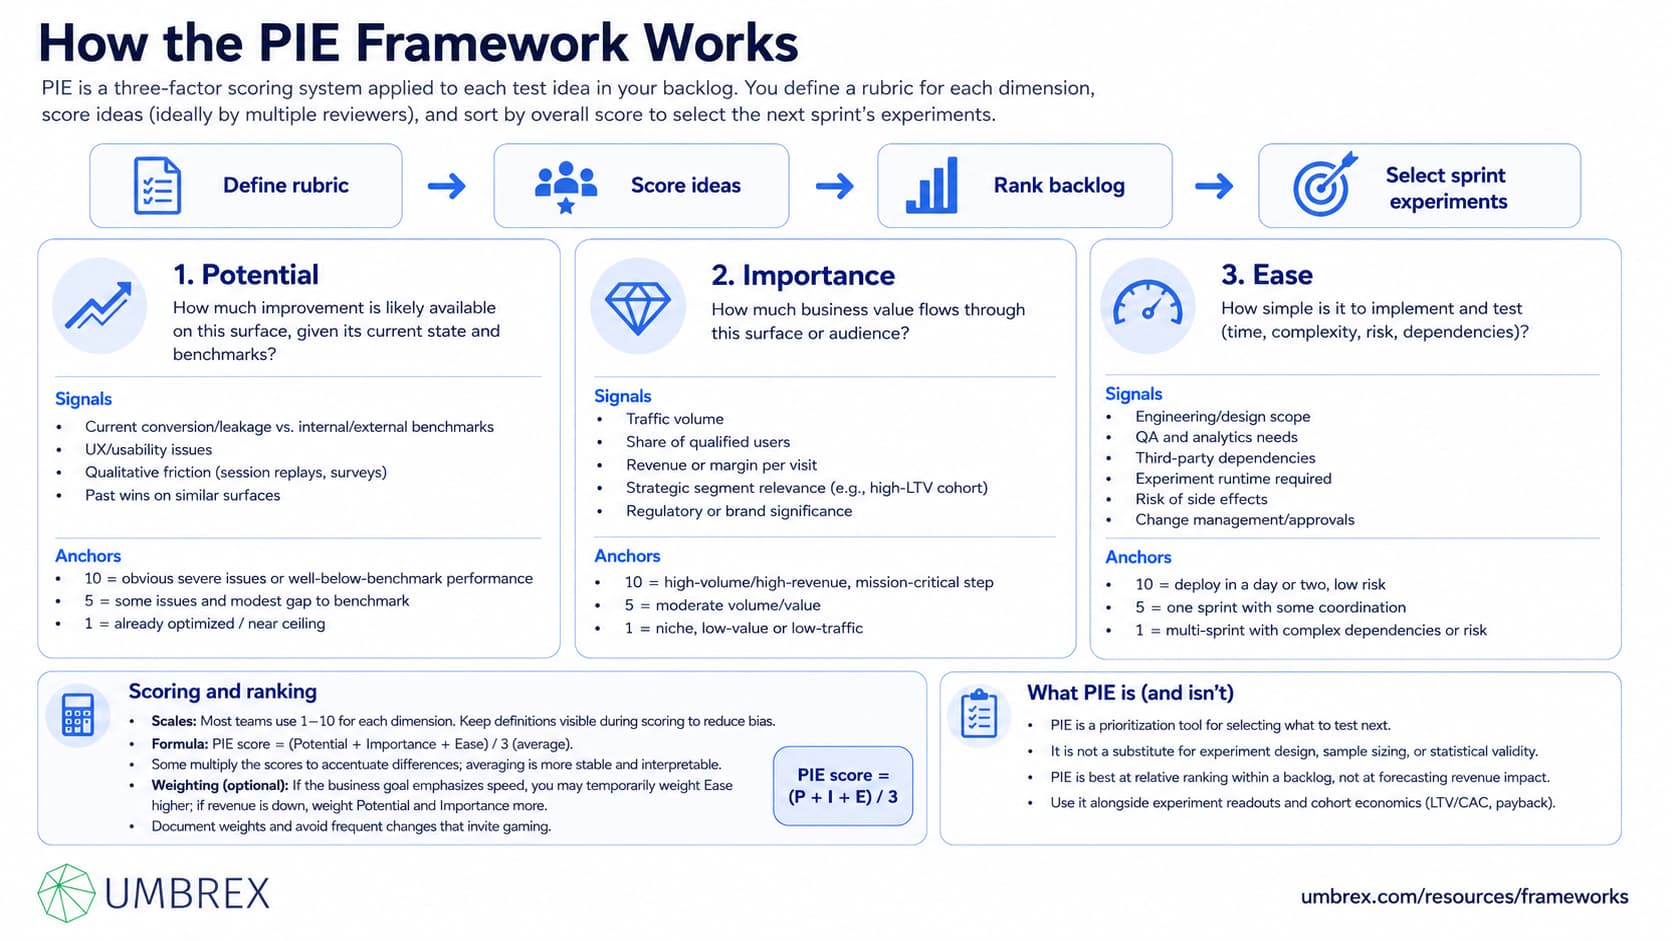
PIE is a three-factor scoring system applied to each test idea in your backlog. You define a rubric for each dimension, score ideas (ideally by multiple reviewers), and sort by overall score to select the next sprint’s experiments.
The three dimensions, defined
- Potential: How much improvement is likely available on this surface, given its current state and benchmarks?
- Signals: Current conversion/leakage vs. internal/external benchmarks; UX/usability issues; qualitative friction (session replays, surveys); past wins on similar surfaces.
- Anchors: 10 = obvious severe issues or well-below-benchmark performance; 5 = some issues and modest gap to benchmark; 1 = already optimized/near ceiling.
- Importance: How much business value flows through this surface or audience?
- Signals: Traffic volume, share of qualified users, revenue or margin per visit, strategic segment relevance (e.g., high-LTV cohort), regulatory or brand significance.
- Anchors: 10 = high-volume/high-revenue, mission-critical step; 5 = moderate volume/value; 1 = niche, low-value or low-traffic.
- Ease: How simple is it to implement and test (time, complexity, risk, dependencies)?
- Signals: Engineering/design scope, QA and analytics needs, third-party dependencies, experiment runtime required, risk of side effects, change management/approvals.
- Anchors: 10 = deploy in a day or two, low risk; 5 = one sprint with some coordination; 1 = multi-sprint with complex dependencies or risk.
Scoring and ranking
- Scales: Most teams use 1–10 for each dimension. Keep definitions visible during scoring to reduce bias.
- Formula: PIE score = (Potential + Importance + Ease) / 3 (average). Some multiply the scores to accentuate differences; averaging is more stable and interpretable.
- Weighting (optional): If the business goal emphasizes speed, you may temporarily weight Ease higher; if revenue is down, weight Potential and Importance more. Document weights and avoid frequent changes that invite gaming.
What PIE is (and isn’t)
- PIE is a prioritization tool for selecting what to test next, not a substitute for experiment design, sample sizing, or statistical validity.
- PIE is best at relative ranking within a backlog, not at forecasting revenue impact. Use it alongside experiment readouts and cohort economics (LTV/CAC, payback).
4. When to Use PIE
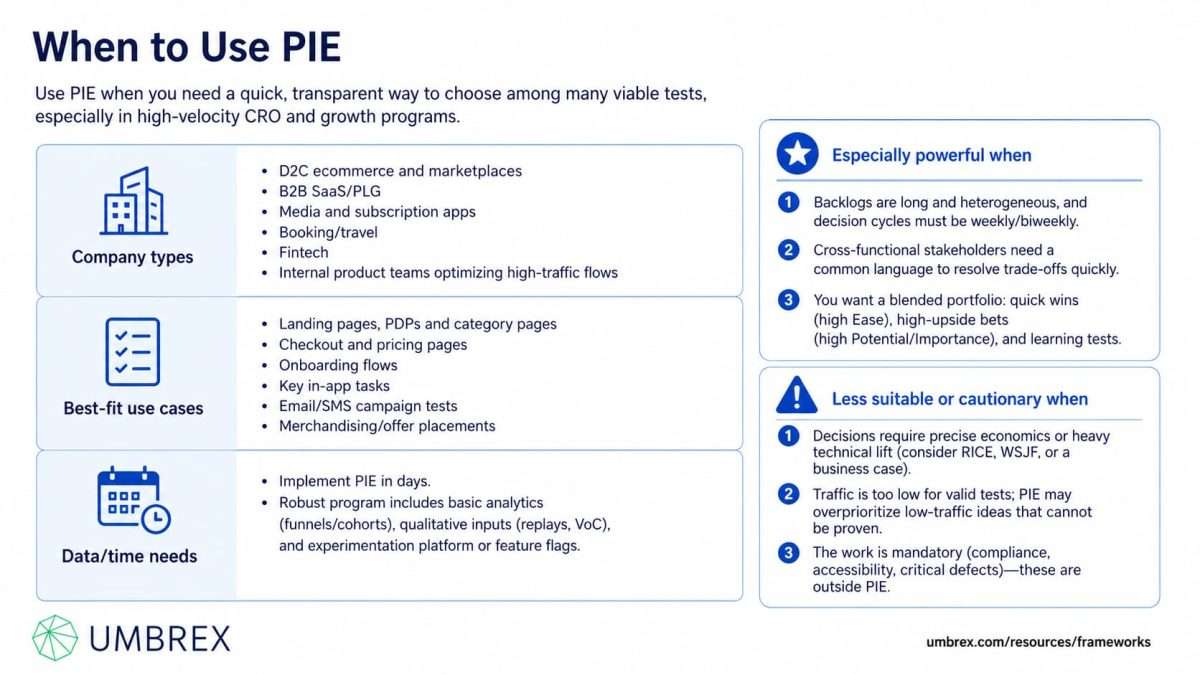
Use PIE when you need a quick, transparent way to choose among many viable tests, especially in high-velocity CRO and growth programs.
- Company types: D2C ecommerce and marketplaces; B2B SaaS/PLG; media and subscription apps; booking/travel; fintech; and internal product teams optimizing high-traffic flows.
- Best-fit use cases: Landing pages, PDPs and category pages, checkout and pricing pages, onboarding flows, key in-app tasks, email/SMS campaign tests, merchandising/offer placements.
- Data/time needs: You can implement PIE in days. A robust program includes basic analytics (funnels/cohorts), qualitative inputs (replays, VoC), and an experimentation platform or feature flags.
Especially powerful when:
- Backlogs are long and heterogeneous, and decision cycles must be weekly/biweekly.
- Cross-functional stakeholders need a common language to resolve trade-offs quickly.
- You want a blended portfolio: quick wins (high Ease), high-upside bets (high Potential/Importance), and learning tests.
Less suitable or cautionary when:
- Decisions require precise economics or entail heavy technical lift (consider RICE, WSJF, or a business case).
- Traffic is too low for valid tests; PIE may overprioritize low-traffic ideas that can’t be proven.
- The work is mandatory (compliance, accessibility, critical defects)—these are outside PIE.
5. How to Apply the PIE Framework: Step-by-Step
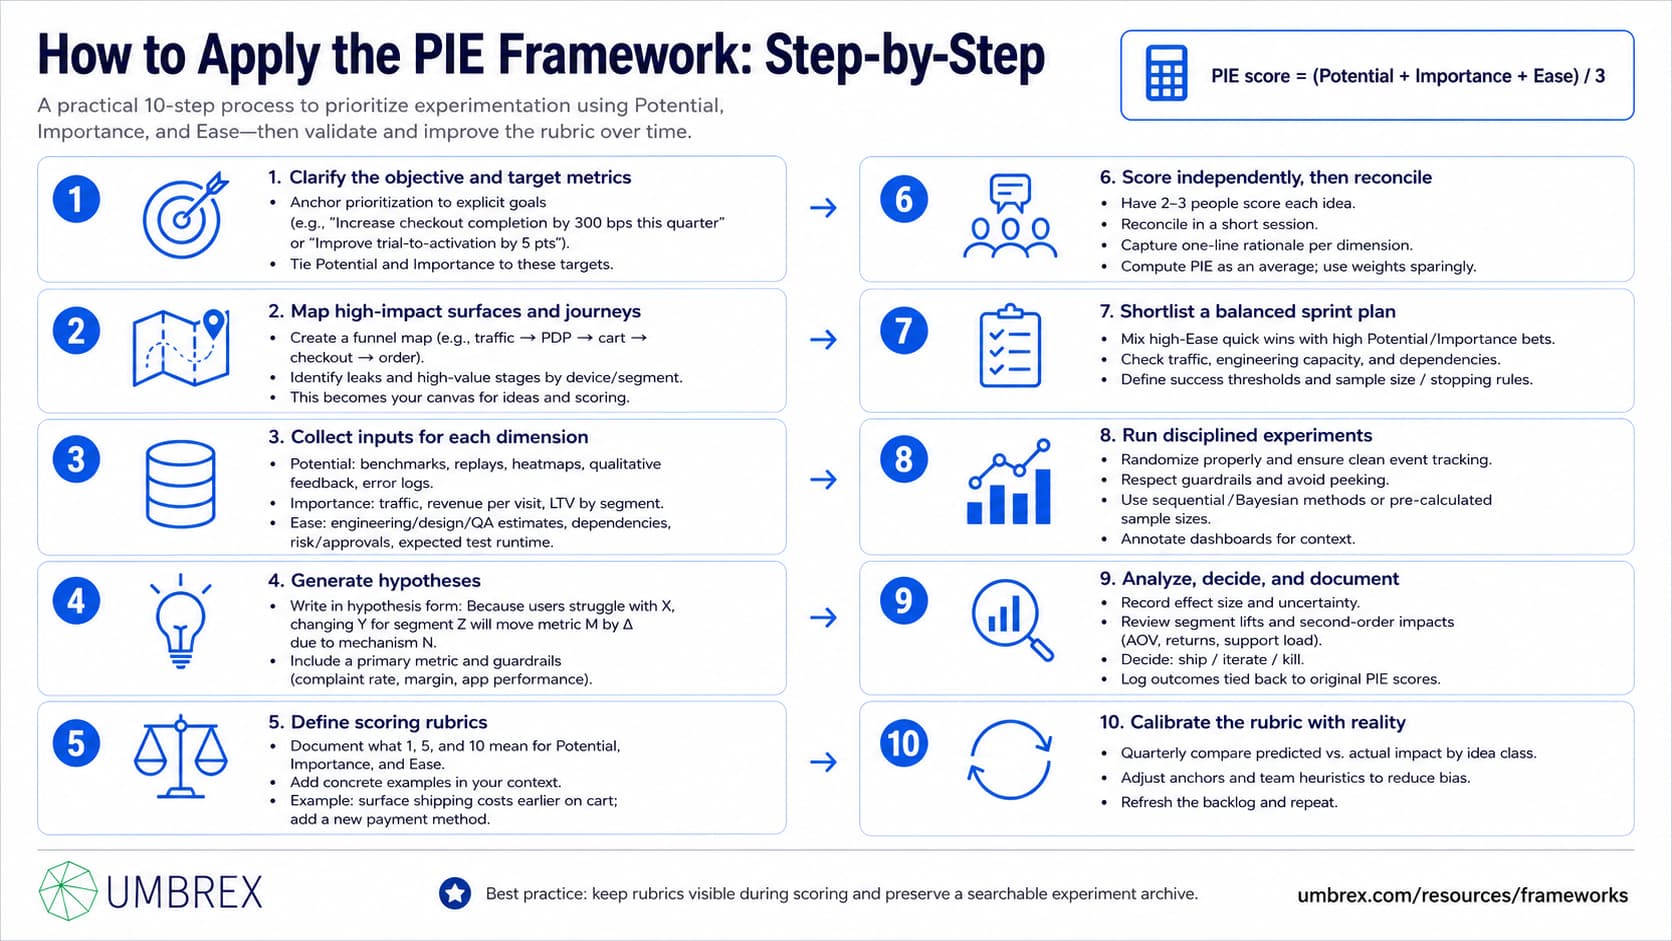
- Clarify the objective and target metrics
Anchor prioritization to explicit goals (e.g., “Increase checkout completion by 300 bps this quarter” or “Improve trial-to-activation by 5 pts”). Tie Potential and Importance to these targets.
- Map high-impact surfaces and journeys
Create a funnel map (e.g., traffic → PDP → cart → checkout → order). Identify leaks and high-value stages by device/segment. This becomes your canvas for ideas and scoring.
- Collect inputs for each dimension
Potential: benchmarks, replays, heatmaps, qualitative feedback, error logs. Importance: traffic, revenue per visit, LTV by segment. Ease: engineering/design/QA estimates, dependencies, risk/approvals, expected test runtime.
- Generate hypotheses
Write test candidates in hypothesis form: “Because users struggle with X (evidence), changing Y for segment Z will move metric M by Δ due to mechanism N.” Include a primary metric and guardrails (complaint rate, margin, app performance).
- Define scoring rubrics
Document what 1, 5, and 10 mean for Potential, Importance, and Ease in your context. Add examples (e.g., moving shipping costs upfront on cart = Potential 6–8 if abandonment is high; adding a new payment method = Ease 5–7 depending on platform).
- Score independently, then reconcile
Have 2–3 people score each idea. Reconcile in a short session, capture rationale in one line per dimension, and compute PIE as an average. Apply any agreed weights sparingly.
- Shortlist a balanced sprint plan
Pick a mix of high-Ease quick wins and high Potential/Importance bets. Check feasibility (traffic for powering tests; engineering capacity; dependencies). Define success thresholds and sample size/stopping rules for each test.
- Run disciplined experiments
Randomize properly, ensure clean event tracking, and respect guardrails. Avoid peeking; use sequential/Bayesian methods or pre-calculated sample sizes. Annotate dashboards for context.
- Analyze, decide, and document
Record effect size and uncertainty, segment lifts, and any second-order impacts (AOV, returns, support load). Decide ship/iterate/kill. Log outcomes in a searchable repository tied to the original PIE scores.
- Calibrate the rubric with reality
Quarterly, compare predicted vs. actual impact by idea class (checkout UX, pricing, PDP content). Adjust scoring anchors and team heuristics to reduce bias. Update your backlog and repeat.
6. Example: PIE in Action
Context: “GearNest,” a $180M D2C outdoor equipment retailer, needed to improve mobile conversion and reduce checkout abandonment. The growth team had 30+ ideas; stakeholders disagreed on priorities.
Objective: +300 bps checkout completion on mobile in 90 days; protect contribution margin and NPS.
Candidate ideas (selected) and PIE scores (average):
- Upfront shipping/returns clarity on cart (copy/design change): Potential 7, Importance 8, Ease 9 → PIE 8.0
- One-page checkout + Apple Pay/Shop Pay: Potential 8, Importance 9, Ease 6 → PIE 7.7
- Guest checkout defaults (email later): Potential 6, Importance 8, Ease 8 → PIE 7.3
- Size & fit guide revamp on PDP: Potential 6, Importance 7, Ease 5 → PIE 6.0
- Free shipping threshold test ($85→$65): Potential 5, Importance 8, Ease 9 (guardrail: margin) → PIE 7.3
- Referral program refresh: Potential 4, Importance 5, Ease 6 → PIE 5.0
Plan: Sprint 1 shipped shipping/returns clarity, guest checkout defaults, and a limited geography pilot for the threshold test. Sprint 2 deployed one-page checkout with accelerated payments and instrumented the PDP fit guide revamp.
Outcomes (8 weeks):
- Checkout completion +410 bps; cart → checkout click-through +240 bps with upfront shipping clarity.
- Apple Pay/Shop Pay drove +620 bps lift on iOS-heavy cohorts; abandonment −12% in the accelerated payments variant.
- Threshold pilot increased AOV +5% but reduced margin by 90 bps; limited rollout with tighter targeting.
- PDP fit guide revamp reduced size-related returns by 7% in affected categories; net revenue improved despite moderate Ease.
- NPS steady; complaint rate unchanged. The team rescored backlog: checkout UX and clarity changes gained higher Confidence and Potential anchors for future cycles.
7. Strengths and Limitations
Strengths
- Simple and fast: Easy to teach and apply weekly; reduces prioritization overhead.
- Cross-functional alignment: Shared, plain-English dimensions everyone understands.
- Evidence-friendly: Encourages data-driven Potential and Importance, and practical Ease estimates.
- Portfolio balance: Mix of quick wins (high Ease) and big bets (high Potential/Importance) supports momentum and learning.
Limitations
- Subjectivity risk: Without clear rubrics and multiple scorers, scores reflect opinions or hierarchy.
- Not a finance model: PIE doesn’t compute LTV/CAC, margin, or payback; pair with economics for larger initiatives.
- Ignores traffic/power by default: High PIE on low-traffic areas can stall if you can’t reach significance.
- Dependency blind spots: High PIE items can be blocked by technical or operational constraints unless you explicitly consider them.
8. Common Pitfalls (and How to Avoid Them)
- Scoring Potential without evidence
What goes wrong: Overestimates; tests underperform.
How to avoid: Use funnels, benchmarks, replays, and VoC to justify Potential; penalize guesses in the rubric.
- Ignoring traffic and runtime
What goes wrong: Tests can’t reach significance; backlog clogs.
How to avoid: Add a “power check” before scheduling; prioritize ideas that can be proven within your traffic constraints.
- Overweighting Ease → superficial tests
What goes wrong: Cosmetic changes crowd out higher-upside work.
How to avoid: Maintain a portfolio rule of thumb (e.g., 40% quick wins, 40% core bets, 20% learning).
- Not accounting for dependencies/risk
What goes wrong: High-PIE items stall; timelines slip.
How to avoid: Include QA, analytics, approvals, and partner/3rd-party work in Ease; label blocked items “not ready.”
- Poor experiment hygiene
What goes wrong: False positives/negatives; wasted cycles.
How to avoid: Define primary metrics, guardrails, sample sizes, and stopping rules; ensure clean instrumentation and randomization.
- Never calibrating scores
What goes wrong: Bias persists; PIE loses credibility.
How to avoid: Quarterly “forecast vs. actual” review; update anchors and team heuristics.
- Using PIE for mandatory work
What goes wrong: Critical compliance or reliability work loses out to “easier” tests.
How to avoid: Pre-screen non-negotiables; PIE is for discretionary, impact-oriented ideas.
9. How PIE Relates to Other Frameworks
- ICE (Impact, Confidence, Ease): Very similar. Potential ≈ Impact (where Impact is the expected effect on a metric). ICE explicitly scores Confidence (evidence strength); PIE infers it via Potential/Importance but you can add a “confidence note.”
- RICE (Reach, Impact, Confidence, Effort): More granular and economics-aware. Use RICE when audience size varies greatly across ideas or when stakes justify more precision. PIE is faster for weekly CRO cadence.
- WSJF (Weighted Shortest Job First): Uses (Cost of Delay ÷ Job Size). Helpful for larger portfolios and platform work; heavier than PIE.
- Growth Hacking Loop (Ideate–Prioritize–Test–Analyze): PIE is the “Prioritize” step—feed ideas from analytics/user research, rank with PIE, then test and learn.
- HEART and AARRR: Use HEART (Task Success, Retention, Happiness) or AARRR stages to choose the target metrics for your tests; PIE helps decide which tests to run first.
- Lean Analytics Stages: Your current stage (e.g., Stickiness vs. Revenue) should influence Potential and Importance definitions; PIE then ranks candidates within that stage.
10. Key Takeaways
- PIE (Potential, Importance, Ease) is a simple scoring model to prioritize experiments and changes quickly and transparently.
- Define clear rubrics and anchor Potential/Importance in data (funnels, value per visit, LTV segments); include full effort and risk in Ease.
- Score independently, reconcile quickly, and pick a balanced portfolio of quick wins and core bets; ensure tests are statistically valid and well-instrumented.
- PIE is for prioritization, not economics—pair with cohort and margin analysis for bigger bets; recalibrate anchors quarterly based on outcomes.
- Use PIE alongside frameworks like ICE/RICE, HEART/AARRR, and a growth loop to create a complete, high-velocity experimentation system.
11. FAQs About the PIE Testing Framework
How is PIE different from ICE or RICE?
PIE and ICE are close cousins: Potential ≈ Impact, Ease is shared, and ICE adds Confidence explicitly. RICE adds Reach and uses Effort instead of Ease. Use PIE when you need speed and ideas affect similar audiences; use RICE when audience size and effort vary widely or stakes are higher.
What scale should we use for scoring?
A 1–10 scale is common, with anchors at 1/5/10 documented for each dimension. Some teams prefer 1–5 to reduce false precision. The key is consistent definitions and multi-rater scoring with reconciliation.
Should we average or multiply the scores?
Averaging (PIE = (P + I + E)/3) yields stable, interpretable results. Multiplying amplifies differences but can be noisy or gameable. If you multiply, cap the scale (e.g., 1–5), normalize, and sanity-check the ranking.
How often should we re-score the backlog?
Re-score monthly or at the start of each sprint cycle, and whenever goals change or you learn something material about feasibility or impact. Archive stale ideas after a quarter unless an owner refreshes them.
Can we apply PIE outside CRO (e.g., features, emails, pricing)?
Yes. PIE works for prioritizing email/SMS tests, onboarding improvements, feature experiments, and even pricing/packaging tests—so long as you define Potential and Importance in terms of the relevant outcome metrics and audiences, and you include implementation/risk in Ease.
What if our traffic is low?
Add a “power check” gate: only schedule tests that can reach significance in an acceptable timeframe or use higher-effect-size changes. Where controlled tests aren’t feasible, run pilots, quasi-experiments (geo/time holdouts), or rely on stronger qualitative and task-based measures until you scale.
How do we prevent bias and score inflation?
Score independently, reconcile with brief rationale per dimension, keep rubrics visible, and run quarterly forecast-vs-actual reviews by idea class. Rotate facilitators and limit weighting changes to once per quarter.
